Introducing Contrastive Language Model (CLM): an ultra-fast System One Model trained with a contrastive learning objective that connects states and actions.
CLM-8B is pre-trained on internet-scale data and delivers up to 9× faster inference than Jev ⚡ while achieving comparable performance across computer-use, gaming, and tool-calling tasks.
With lightweight fine-tuning, CLM-8B sets a new SOTA on challenging agentic coding benchmarks, such as DeepSWE (81.6%) and Terminal-Bench 2.1 (87.6%). In contrast, Jev fails to serve as an effective verifier for these long-horizon tasks.
We also build an efficient training and serving infra for CLMs by disaggregating states and actions, allowing their embeddings to be cached and reused independently. This substantially reduces inference latency in settings where the state evolves continuously while the action set remains fixed.
Finally, we establish scaling laws for CLMs and show that the test contrastive loss decreases predictably as a power law in training compute, model size, and dataset size.
📄 Blog: contrastive-lm.notion.site
💻 Code: github.com/Contrastive-LM/CLM
🗣️ Discord: discord.gg/5dAQEDJBs
🤗 Data & Models: huggingface.co/Contrastive-LM
More details on CLM’s architecture, data recipe, and scaling laws in the thread below 🧵
Jacky Kwok
@jackyk02
🧵(1) Model Architecture
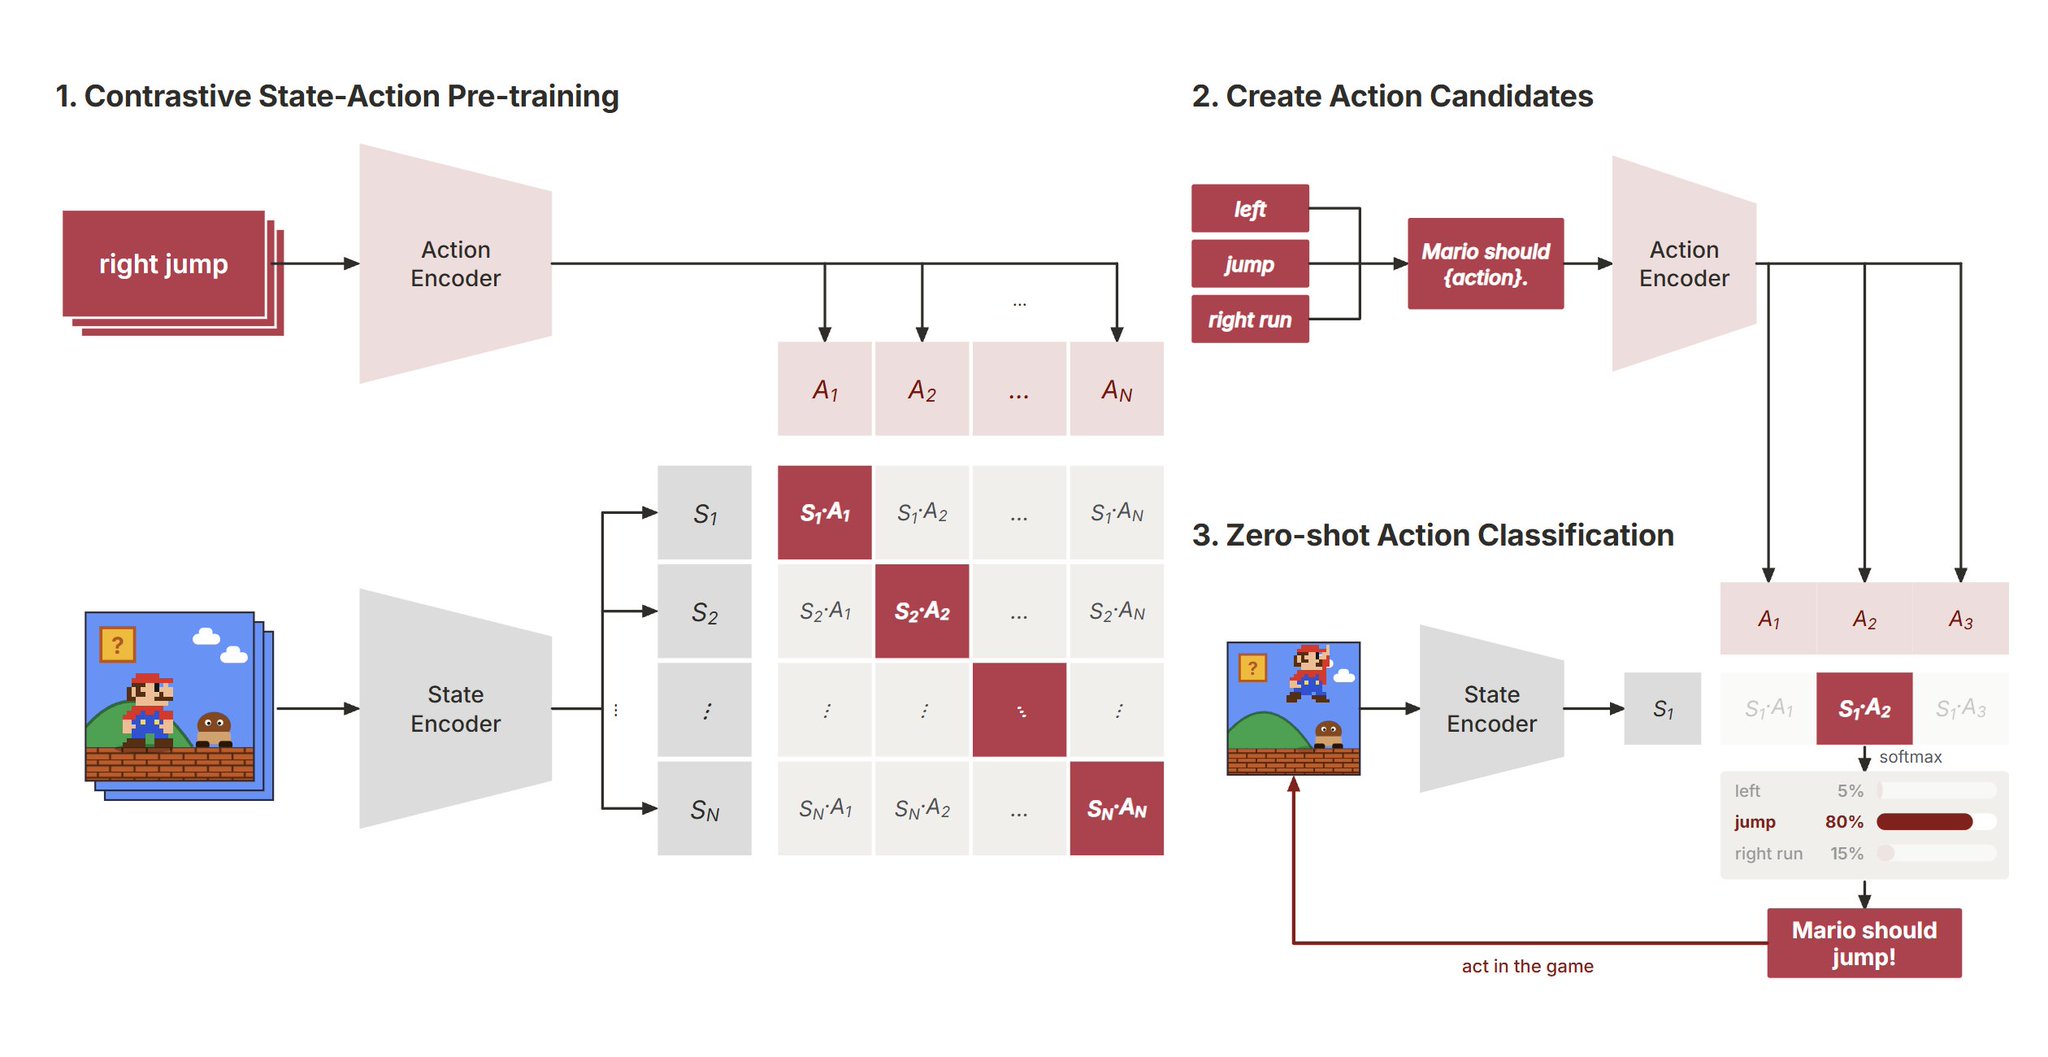
CLM first trains a state encoder and an action encoder on a large-scale dataset with a contrastive objective, so that each state is pulled toward the ground-truth action and pushed away from all others. The two encoders then serve directly as a zero-shot action classifier.
CLM first trains a state encoder and an action encoder on a large-scale dataset with a contrastive objective, so that each state is pulled toward the ground-truth action and pushed away from all others. The two encoders then serve directly as a zero-shot action classifier.
11:42 PM UTC · Sep 23, 2026 · 29K Views
2715365
Jacky Kwok
@jackyk02
🧵(2) Data Recipe
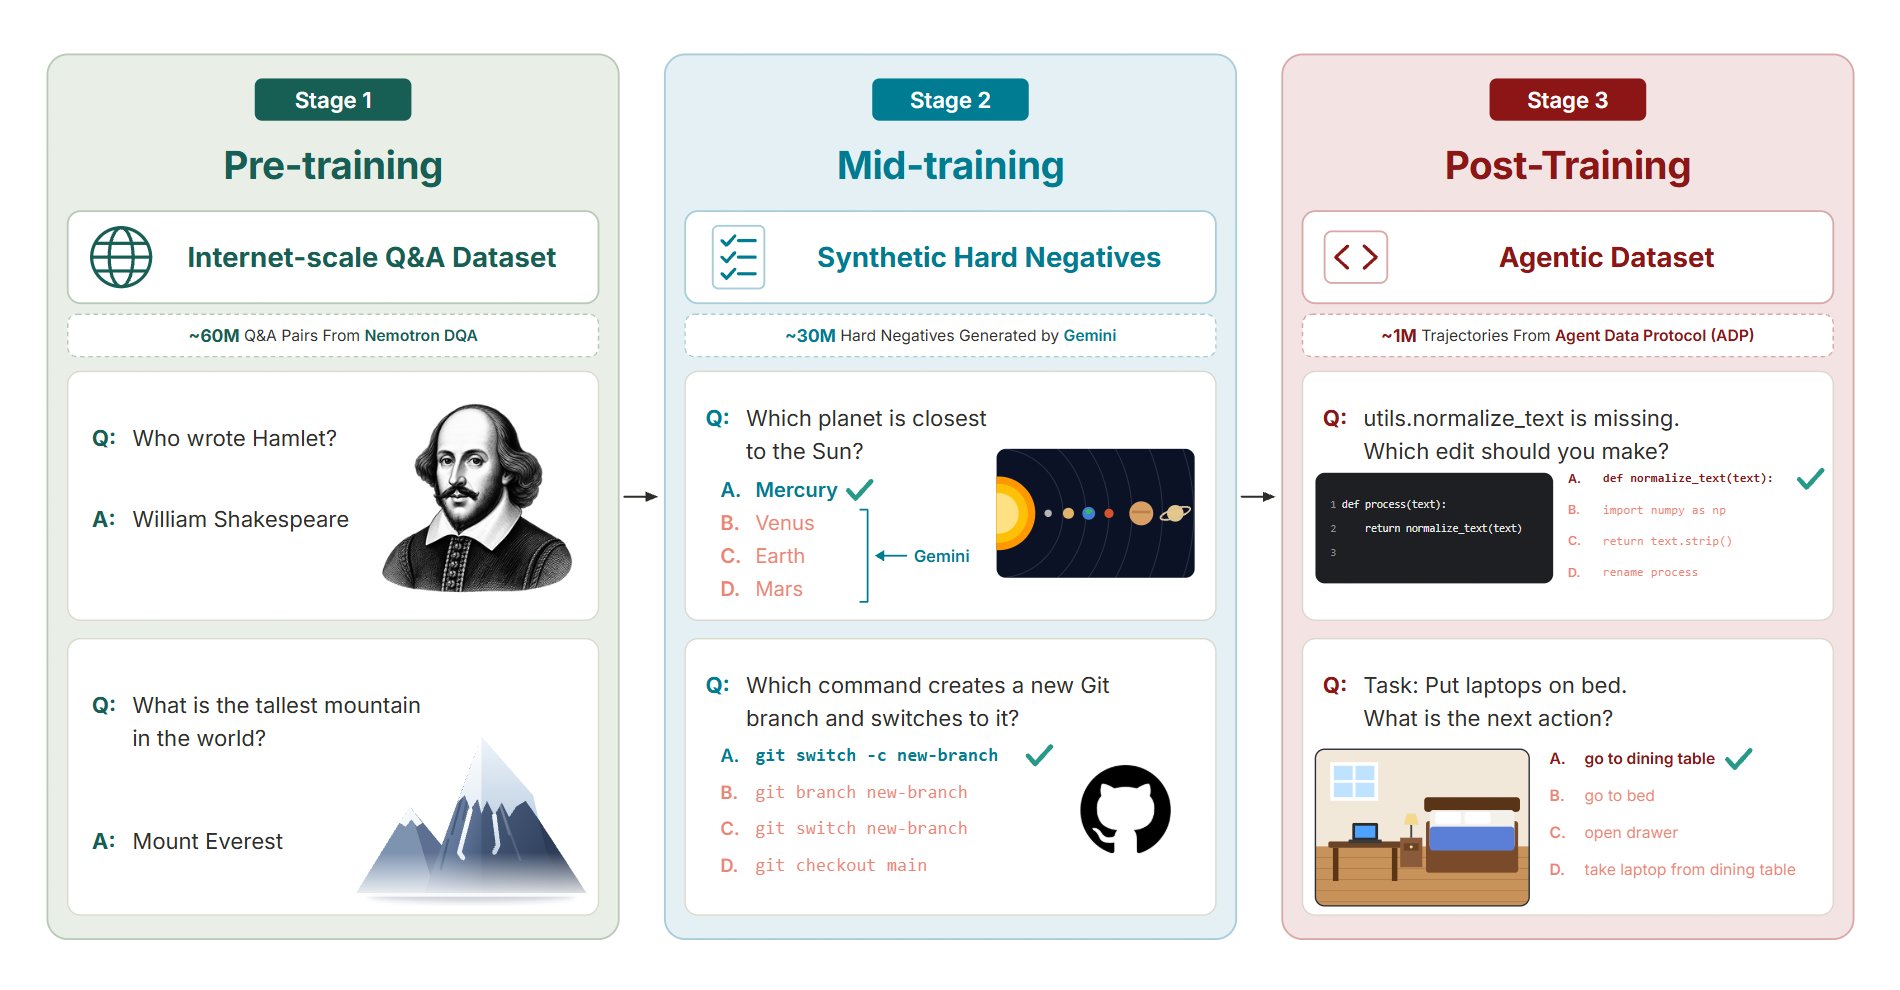
We release CLM-8B, which is pre-trained on 60M Nemotron Q&A pairs, mid-trained on 30M synthetic hard negatives, and post-trained on 1M agentic trajectories.
We release CLM-8B, which is pre-trained on 60M Nemotron Q&A pairs, mid-trained on 30M synthetic hard negatives, and post-trained on 1M agentic trajectories.
11:42 PM UTC · Sep 23, 2026 · 19.5K Views
2710136
Jacky Kwok
@jackyk02
🧵(3) Scaling Laws for Verification
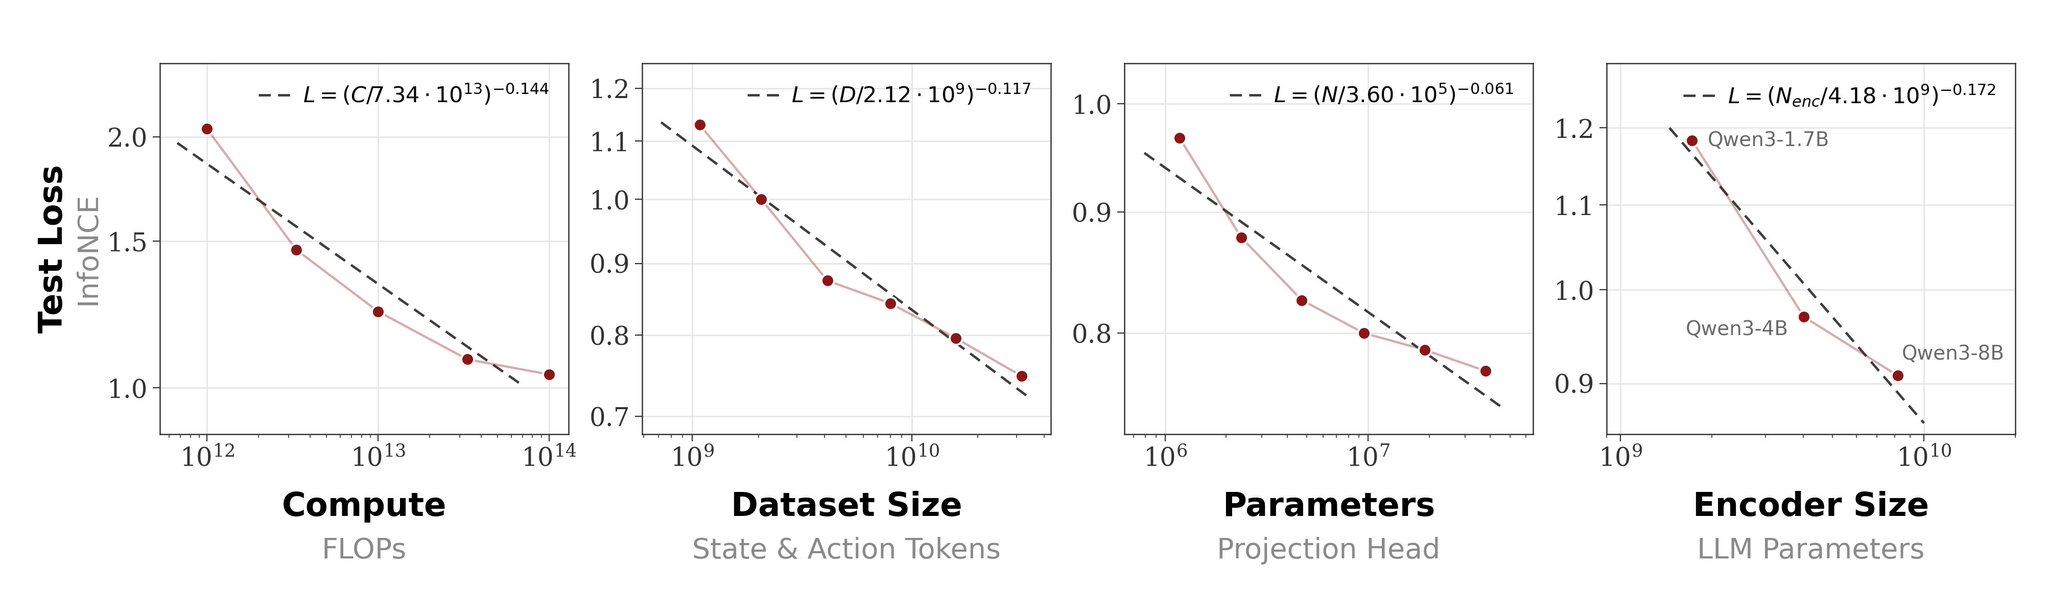
We find that the test InfoNCE loss scales as a power law with training compute, dataset size, projection-head size, and encoder size. These dimensions must be scaled jointly to achieve optimal performance. Notably, scaling the encoder size yields the strongest gains.
We find that the test InfoNCE loss scales as a power law with training compute, dataset size, projection-head size, and encoder size. These dimensions must be scaled jointly to achieve optimal performance. Notably, scaling the encoder size yields the strongest gains.
11:43 PM UTC · Sep 23, 2026 · 21.3K Views
236823
Jacky Kwok
@jackyk02
🧵(4) Latency vs. Jev and Constrained Decoding
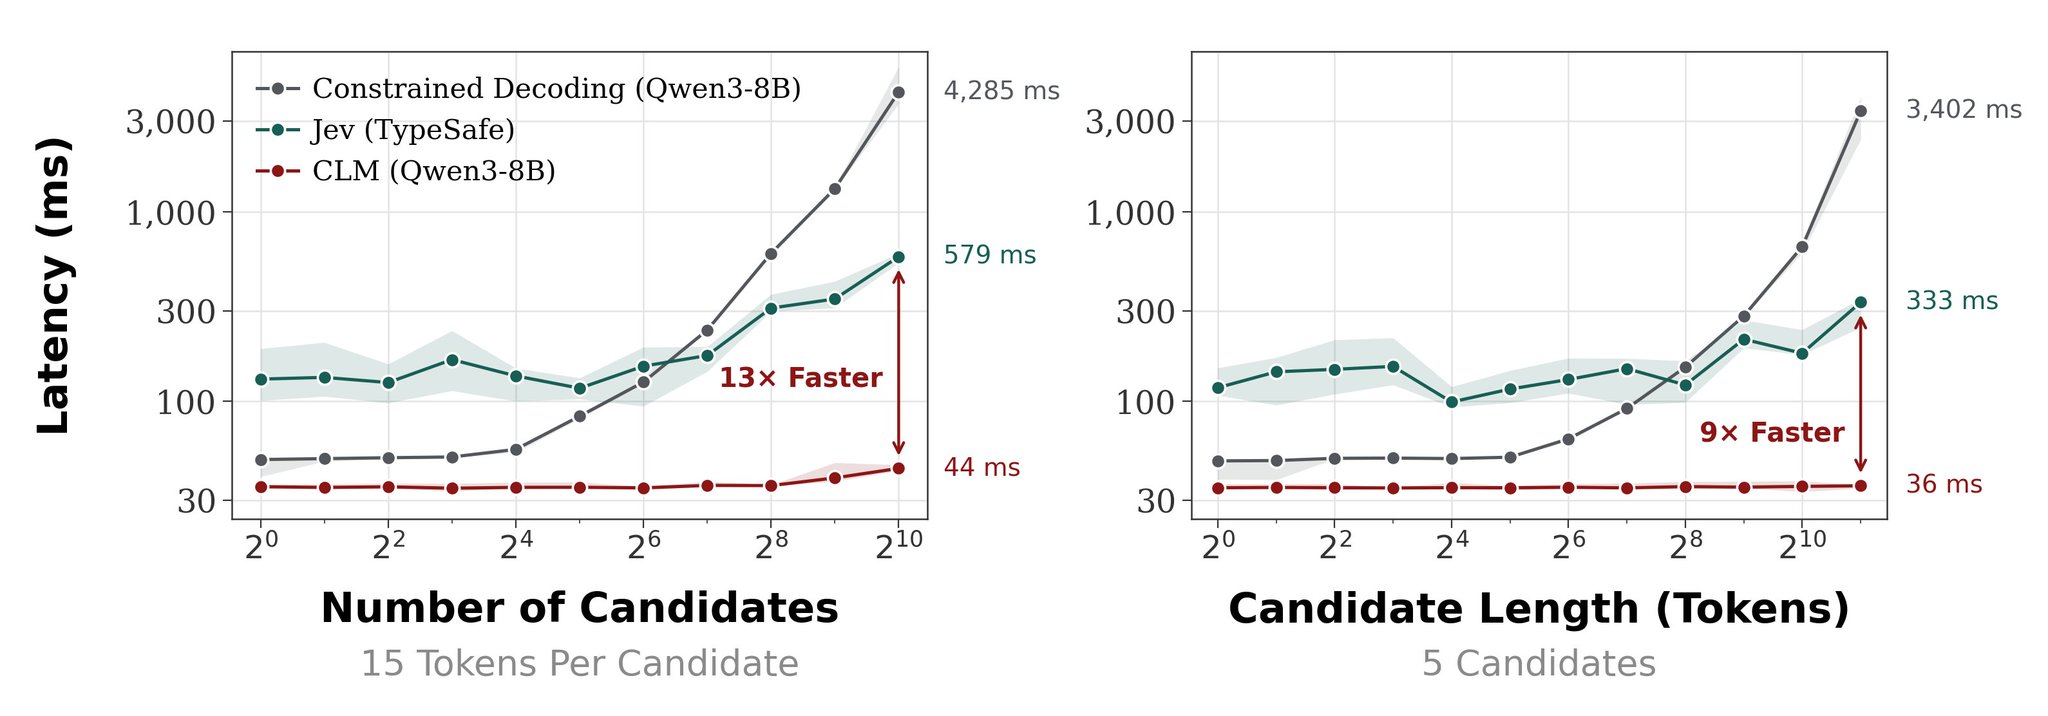
The key difference between CLM and Jev is that Jev only supports state caching, whereas CLM’s dual-encoder architecture allows state and action embeddings to be cached independently.
This is particularly useful in applications such as tool calling, computer use, and games, where the action space is predefined and remains fixed.
By caching the action embeddings, CLM substantially reduces inference cost, with the efficiency gains becoming even larger as the number and length of candidate actions grow. At ~1K candidates, CLM is 13× faster than Jev ⚡
11:51 PM UTC · Sep 23, 2026 · 14.6K Views
157623
Jacky Kwok
@jackyk02
🧵(5) Zero-Shot Evaluation
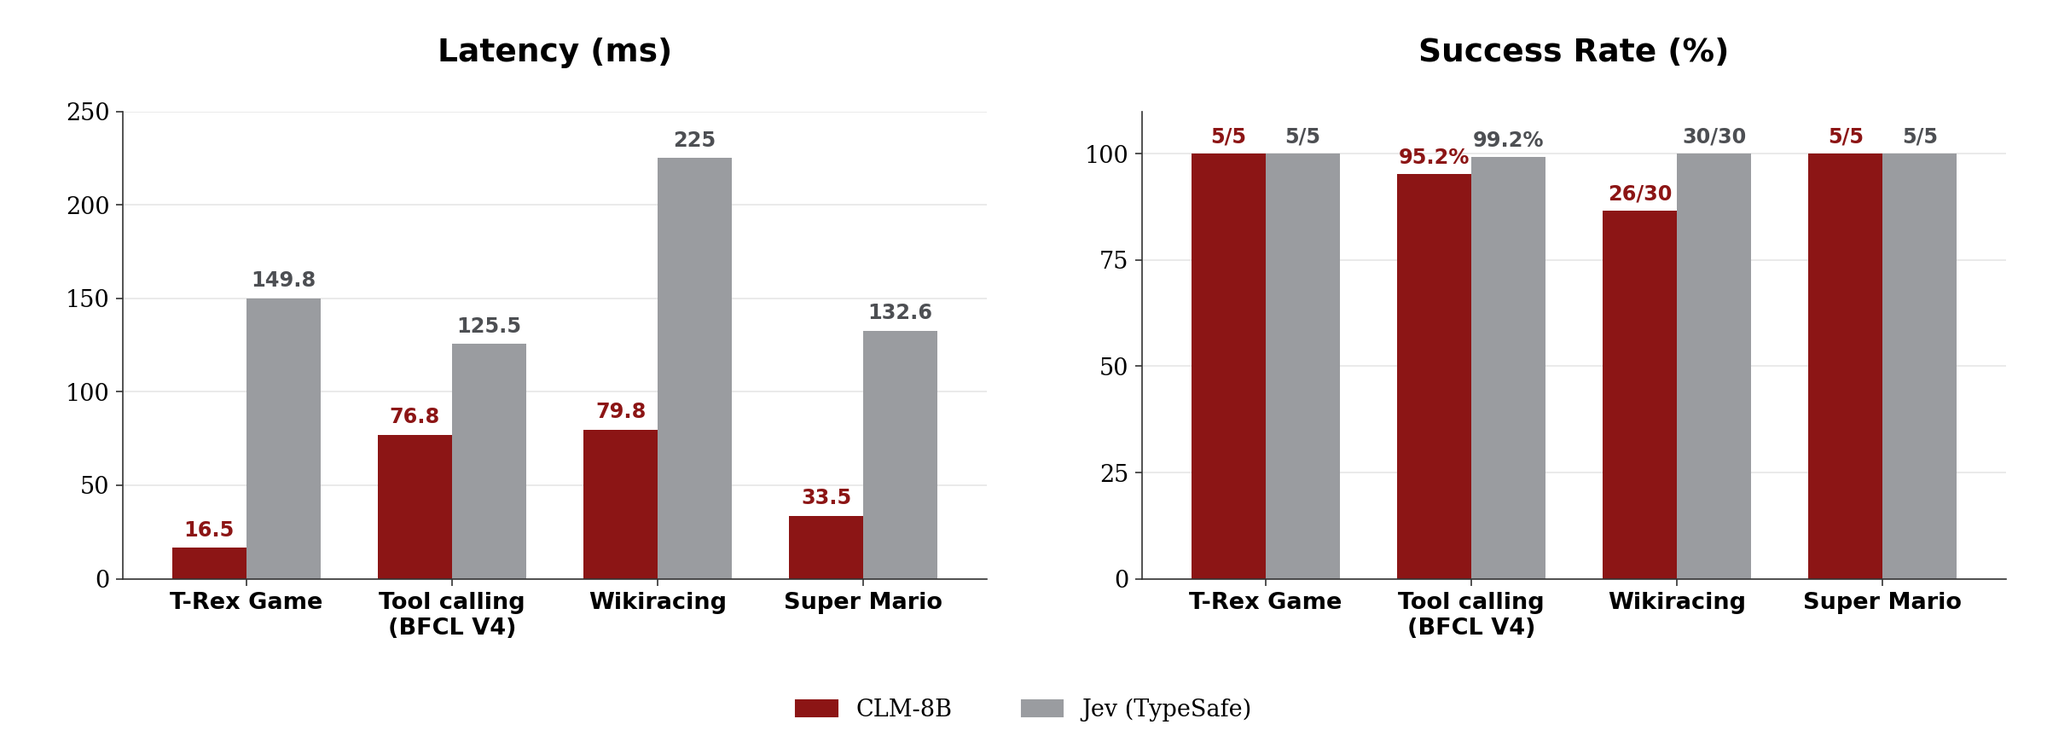
Across computer-use, gaming, and tool-calling tasks, CLM-8B performs on par with Jev while running up to 9× faster. The speedups are most pronounced when the number of candidates is large (e.g., WikiRacing) or when actions can be reused frequently across states (e.g., T-Rex Game).
CLM-35B, with improved generalization and even greater speedups, will be released early next month.
11:52 PM UTC · Sep 23, 2026 · 19.8K Views
137023
Jacky Kwok
@jackyk02
🧵(6) Agentic Benchmarks
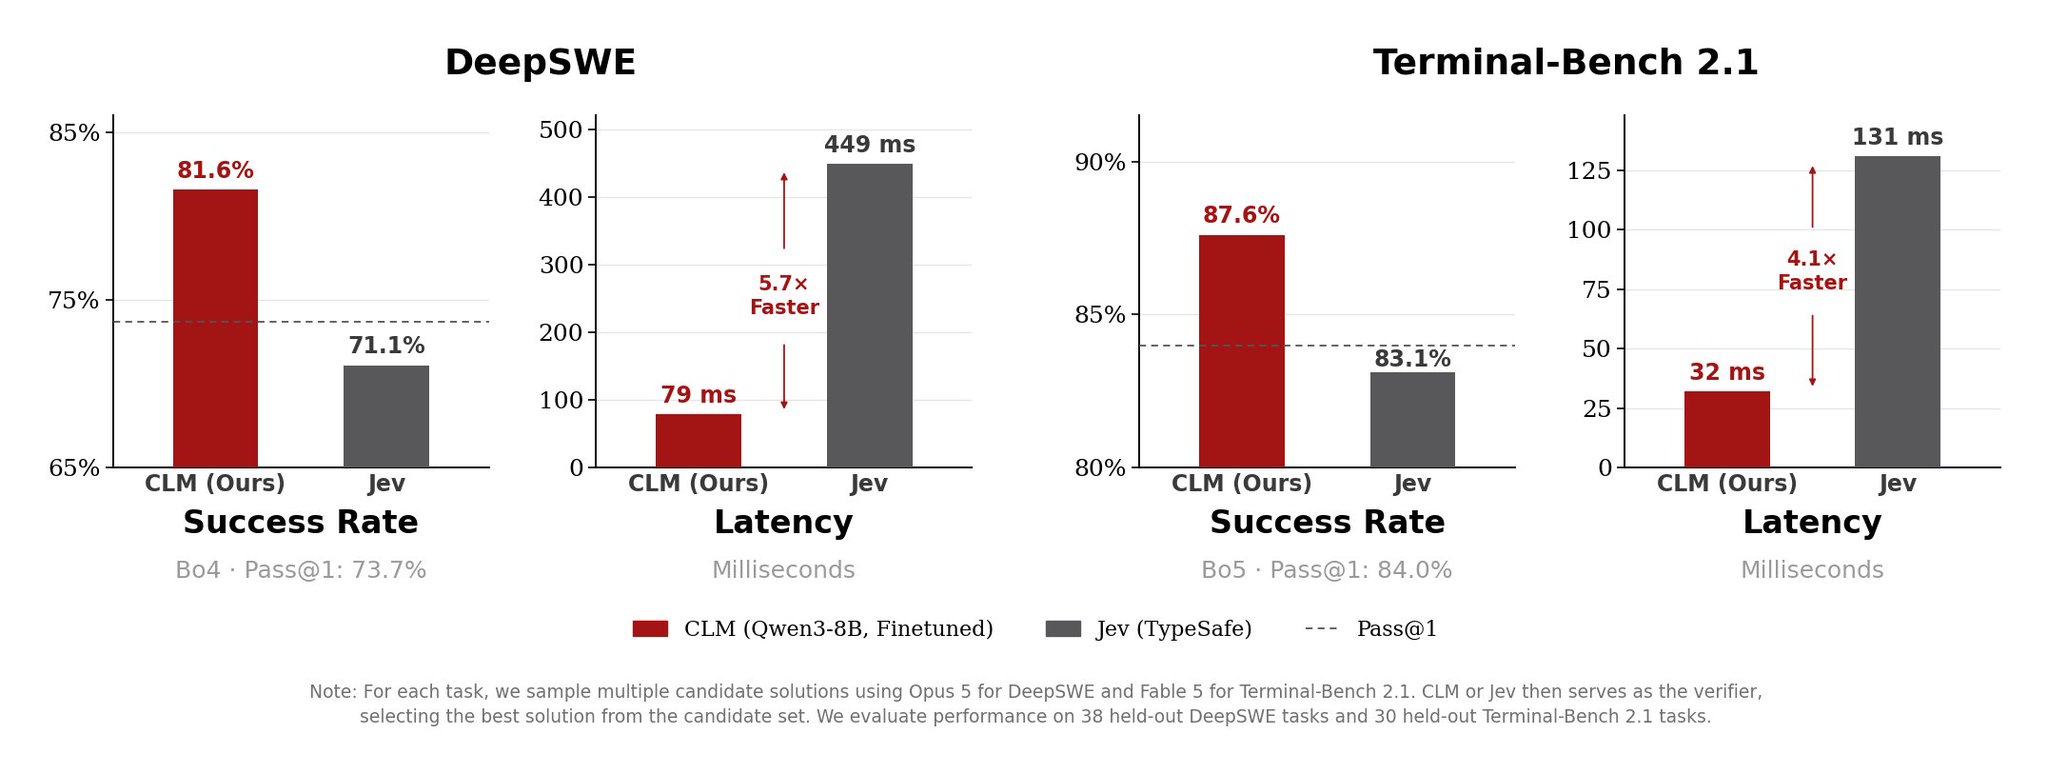
We find that Jev fails to serve as a verifier for long-horizon tasks, performing below the random-selection (Pass@1) baseline.
In contrast, with lightweight fine-tuning, CLM achieves SOTA performance on challenging agentic benchmarks, including DeepSWE (81.6%) and Terminal-Bench 2.1 (87.6%), while delivering 4–6× faster inference than Jev.
11:55 PM UTC · Sep 23, 2026 · 13.2K Views
215722
Jacky Kwok
@jackyk02
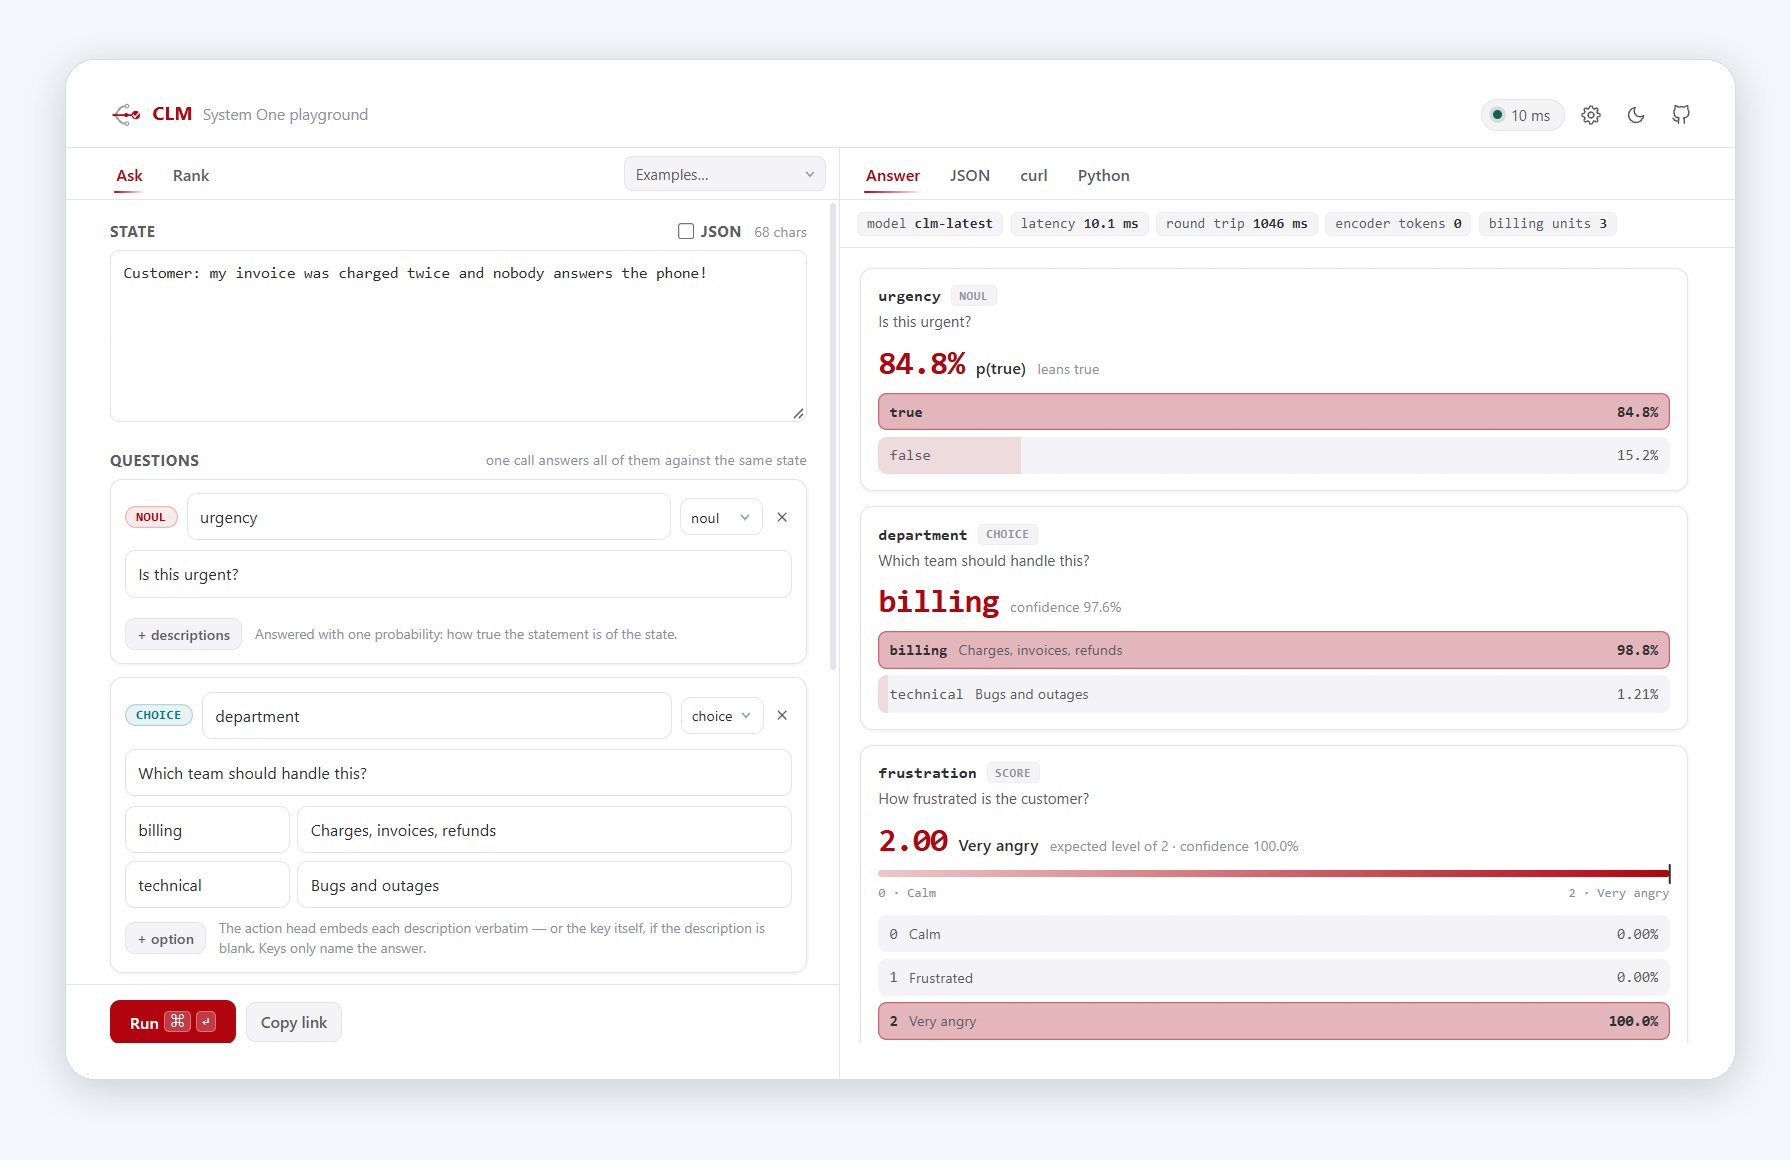
CLM comes with an interactive playground on GitHub: github.com/Contrastive-LM…
11:59 PM UTC · Sep 23, 2026 · 10.5K Views
137142
Jacky Kwok
@jackyk02
CLM-8B is part of our scaling ladder, where we train models across multiple scales to establish scaling laws and predict performance at larger scales. A multimodal CLM-35B is now in training with more data, compute, and parameters. Stay tuned for the release early next month 🚀
12:00 AM UTC · Sep 24, 2026 · 10.5K Views
336814
Jacky Kwok
@jackyk02
Joint work with @hangoo_kang @TarunSures41845 @JonSaadFalcon @drmapavone @Azaliamirh and @HazyResearch
12:01 AM UTC · Sep 24, 2026 · 9.6K Views
305010
Jacky Kwok
@jackyk02
We actually released a robotics version of CLM earlier this year! Check out the CoVer-VLA paper to see how this idea extends to robotics 🤖: arxiv.org/pdf/2602.12281
8:53 PM UTC · Sep 24, 2026 · 2.7K Views
11247