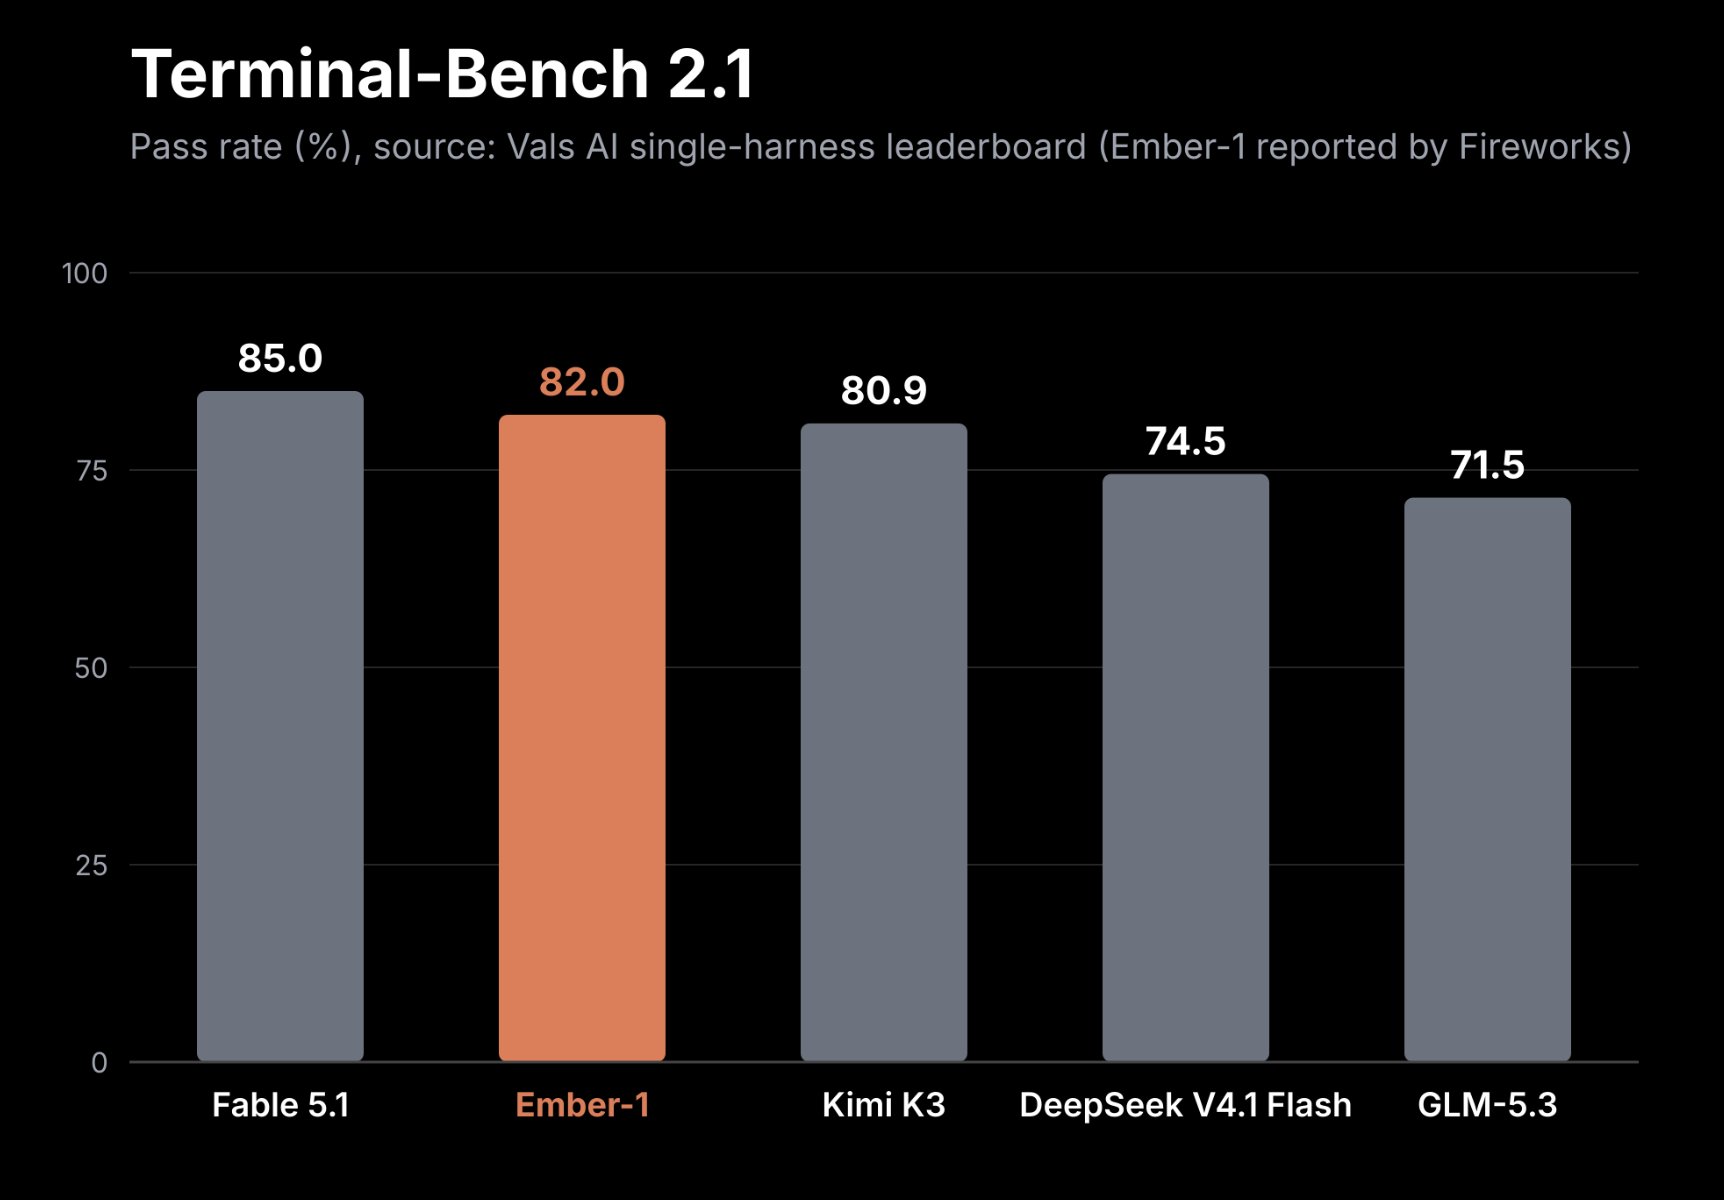
Ember-1 by the Fireworks Research team is built on Kimi K3, and uses ~40% fewer tokens while achieving the same performance on benchmarks.
This was accomplished by post-training K3 to think less repetitively.
Reasoning models spend most of their output tokens (sometimes 90%+) on thinking before they answer, which gets expensive in agentic loops where the model tends to re-think the same thoughts on every step.
Fireworks RL trained on real agentic coding task loops to teach the model which reasoning actually changes the answer vs which is just looping.
In a live A/B test on coding traffic, Ember-1 used 71% fewer reasoning tokens and 39% fewer total tokens than K3 at the same success rate.
Cline
@cline
This is the first model out of the new Fireworks Research team - it’s wonderful to see an inference provider doing post-training on open weights to reduce costs.
Great work @FireworksAI_HQ 💪
fireworks.ai/blog/ember-1
Great work @FireworksAI_HQ 💪
fireworks.ai/blog/ember-1
fireworks.ai
Introducing Ember-1
Ember-1 is a new specialized model from Fireworks Research that delivers Kimi K3’s quality with 40% fewer tokens.
9:58 PM UTC · Sep 27, 2026 · 4.5K Views
20385
Cline
@cline
Available in Cline now, it's especially cool seeing the quicker thinking in our new Desktop app!
cline.bot/desktop
cline.bot/desktop
cline.bot
Cline - AI Coding, Open Source and Open Choice
Open-source AI coding agent with Plan/Act modes, MCP integration, and terminal-first workflows. Trusted by 11M+ developers worldwide.
9:58 PM UTC · Sep 27, 2026 · 3.5K Views
10161