We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weight-space-pro…
Rikiya Takehi
@rikiyatakehi
1/6 We find early signs that frontier LLMs are surprisingly good at *natively* reading, writing, and reasoning about neural network weights.
Instead of training, models may treat raw weights like readable, editable code: diagnosing failures and patching them directly.
Instead of training, models may treat raw weights like readable, editable code: diagnosing failures and patching them directly.
5:51 PM UTC · Nov 2, 2026 · 340.3K Views
12572.7K213
Rikiya Takehi
@rikiyatakehi
2/6 First, a look at understandability:
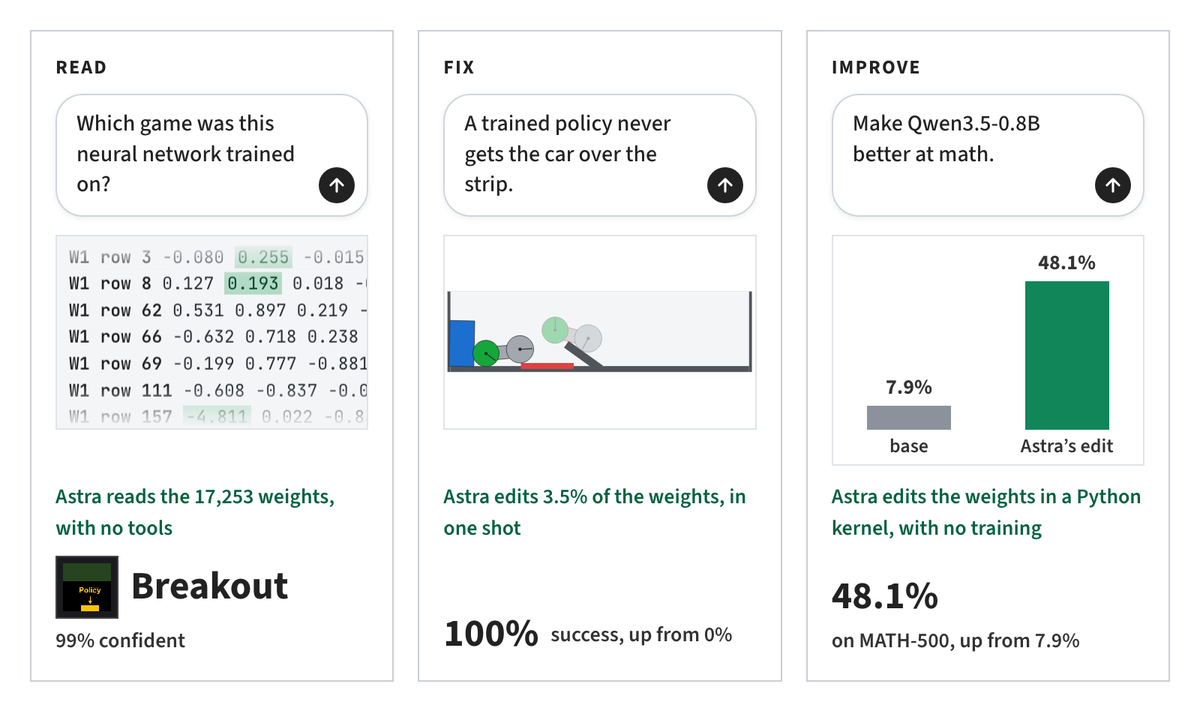
We fed Astra raw weights from 4 game policies one at a time. All four share the exact same architecture, inputs, and actions.
With no tools or options given, it correctly named all four: Breakout, Pong, Pac-Man, Freeway.
We fed Astra raw weights from 4 game policies one at a time. All four share the exact same architecture, inputs, and actions.
With no tools or options given, it correctly named all four: Breakout, Pong, Pac-Man, Freeway.
5:51 PM UTC · Nov 2, 2026 · 290.7K Views
4332K219
Rikiya Takehi
@rikiyatakehi
3/6 Next, fixing weights: A PPO car policy kept getting stuck on a ramp.
Given the weights, scene, and 1 failed trace, Astra wrote a patch in one reply with no tool-use.
By editing just 3.5% of the weights, it achieved 100% success.
Given the weights, scene, and 1 failed trace, Astra wrote a patch in one reply with no tool-use.
By editing just 3.5% of the weights, it achieved 100% success.
5:51 PM UTC · Nov 2, 2026 · 219.8K Views
5181.5K116
Rikiya Takehi
@rikiyatakehi
4/6 Writing from scratch: given MinAtar game rules and code, Astra wrote a Breakout network's weights in a single reply.
With zero training or tools, it scored 20× higher than PPO trained for 500M steps!
With zero training or tools, it scored 20× higher than PPO trained for 500M steps!
5:52 PM UTC · Nov 2, 2026 · 229.3K Views
13231.4K133
Rikiya Takehi
@rikiyatakehi
5/6 Can an LLM improve another LLM?
We simply asked Astra to make Qwen3.5-0.8B better at math.
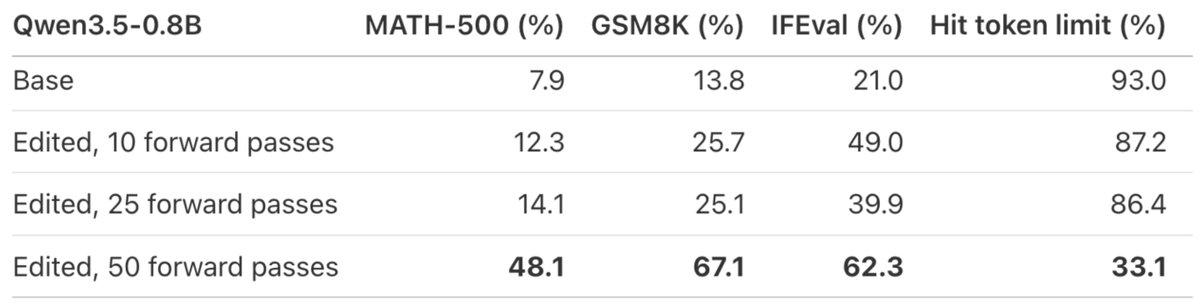
Astra saw Qwen get stuck in reasoning loops, which is a known issue that Qwen’s own model card warns about (see their official model card). With a budget of 50 forward passes on practice problems, it located the cause and edited it out. This used no gradients or training.
Fixing these loops by editing just 0.016% of weights boosted other capabilities beyond math too!
We simply asked Astra to make Qwen3.5-0.8B better at math.
Astra saw Qwen get stuck in reasoning loops, which is a known issue that Qwen’s own model card warns about (see their official model card). With a budget of 50 forward passes on practice problems, it located the cause and edited it out. This used no gradients or training.
Fixing these loops by editing just 0.016% of weights boosted other capabilities beyond math too!
5:52 PM UTC · Nov 2, 2026 · 191.9K Views
12331.9K201
Rikiya Takehi
@rikiyatakehi
6/6 We think neural network weights will soon be natively optimized by LLMs that deliberately reason about the weights.
We are now building a benchmark to evaluate, and a harness to help LLMs explore and write weights.
rikiyat.github.io/blog/weight-sp…
We are now building a benchmark to evaluate, and a harness to help LLMs explore and write weights.
rikiyat.github.io/blog/weight-sp…
rikiyat.github.io
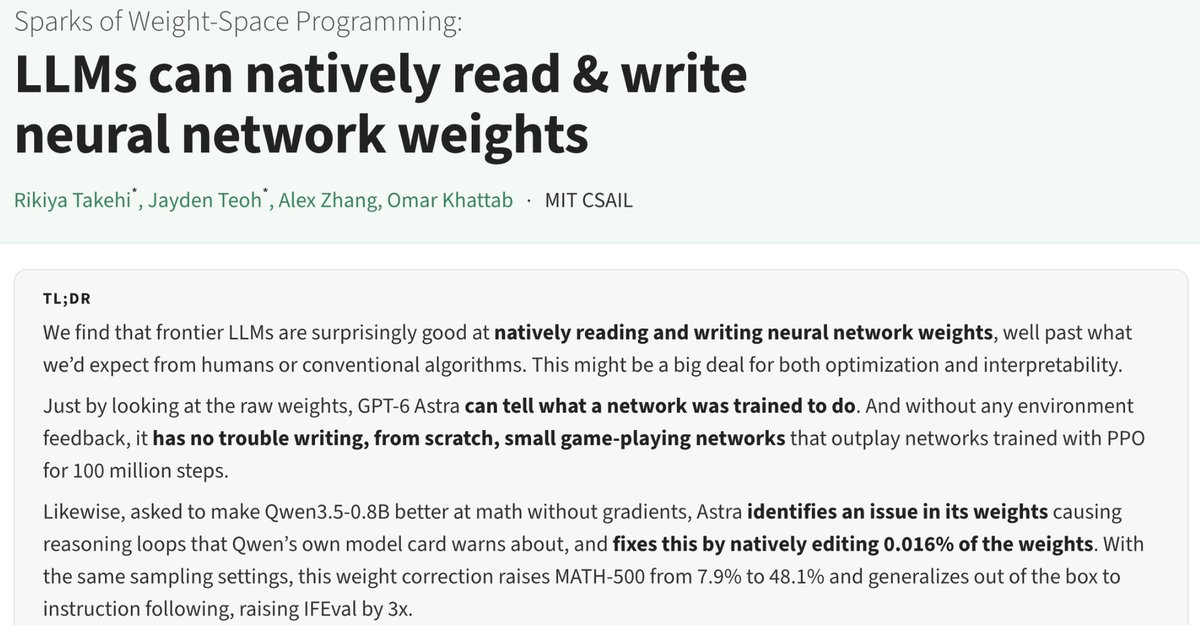
Sparks of Weight-Space Programming: LLMs can natively read & write neural network weights
We find that frontier LLMs are surprisingly good at natively reading and writing neural network weights, well past what we’d expect from humans or conventional algorithms.
5:52 PM UTC · Nov 2, 2026 · 174.1K Views
64752.6K600