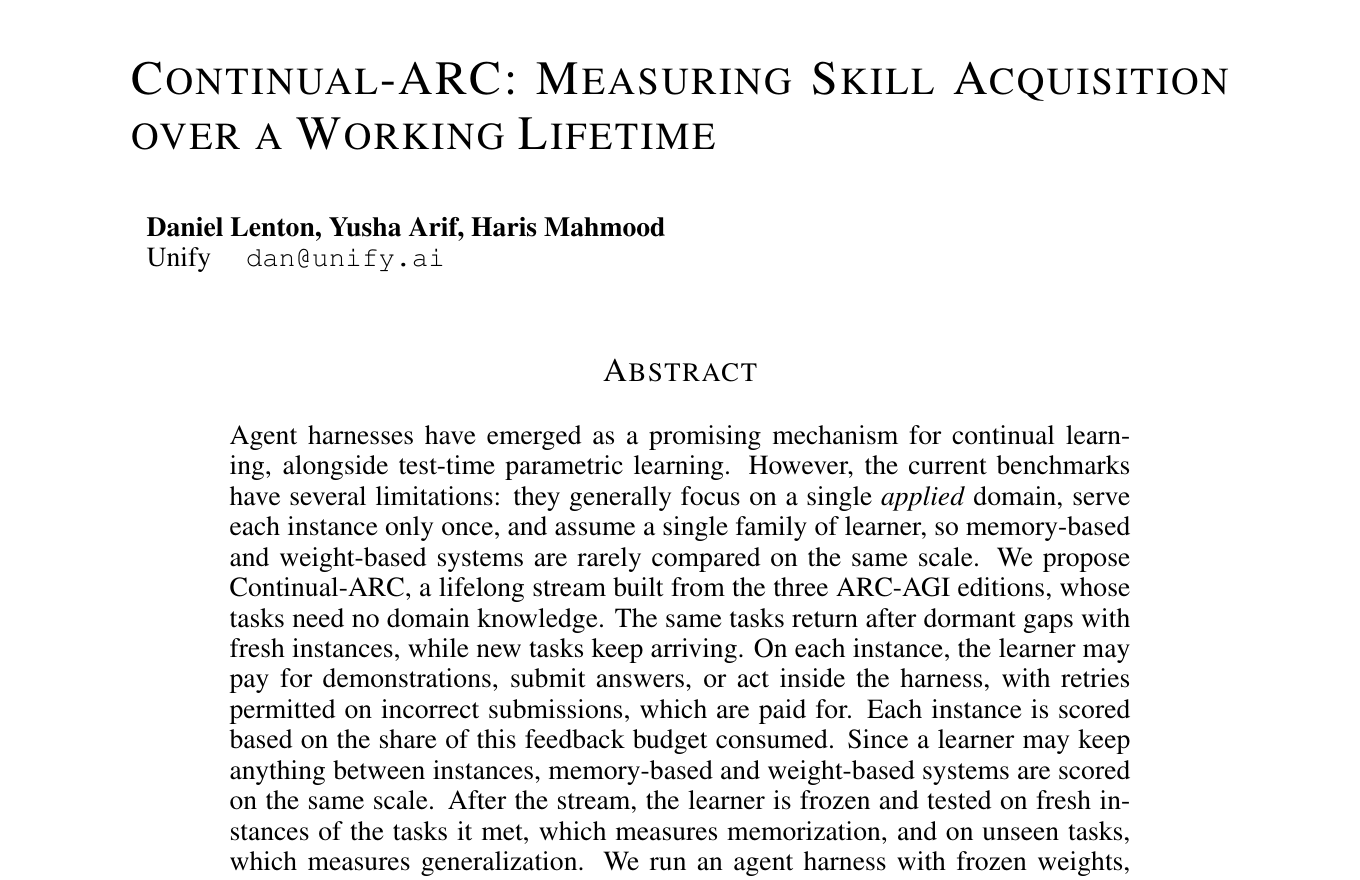
OpenClaw, Hermes Agent and Prime Agent don't meaningfully learn from experience.
On Continual-ARC, our new benchmark at @letsunifyai, none of them were able to memorize anything of value and none were able to generalize to new tasks. Training a small 9B model's weights did both.
Daniel Lenton
@DanielLenton1
The paper, the code, and replays of every run:
Paper: unify.ai/papers/continu…
Code: github.com/unifyai/contin…
Site: continual-arc.unify.ai
Paper: unify.ai/papers/continu…
Code: github.com/unifyai/contin…
Site: continual-arc.unify.ai
3:12 PM UTC · Nov 11, 2026 · 9.2K Views
1919990
Daniel Lenton
@DanielLenton1
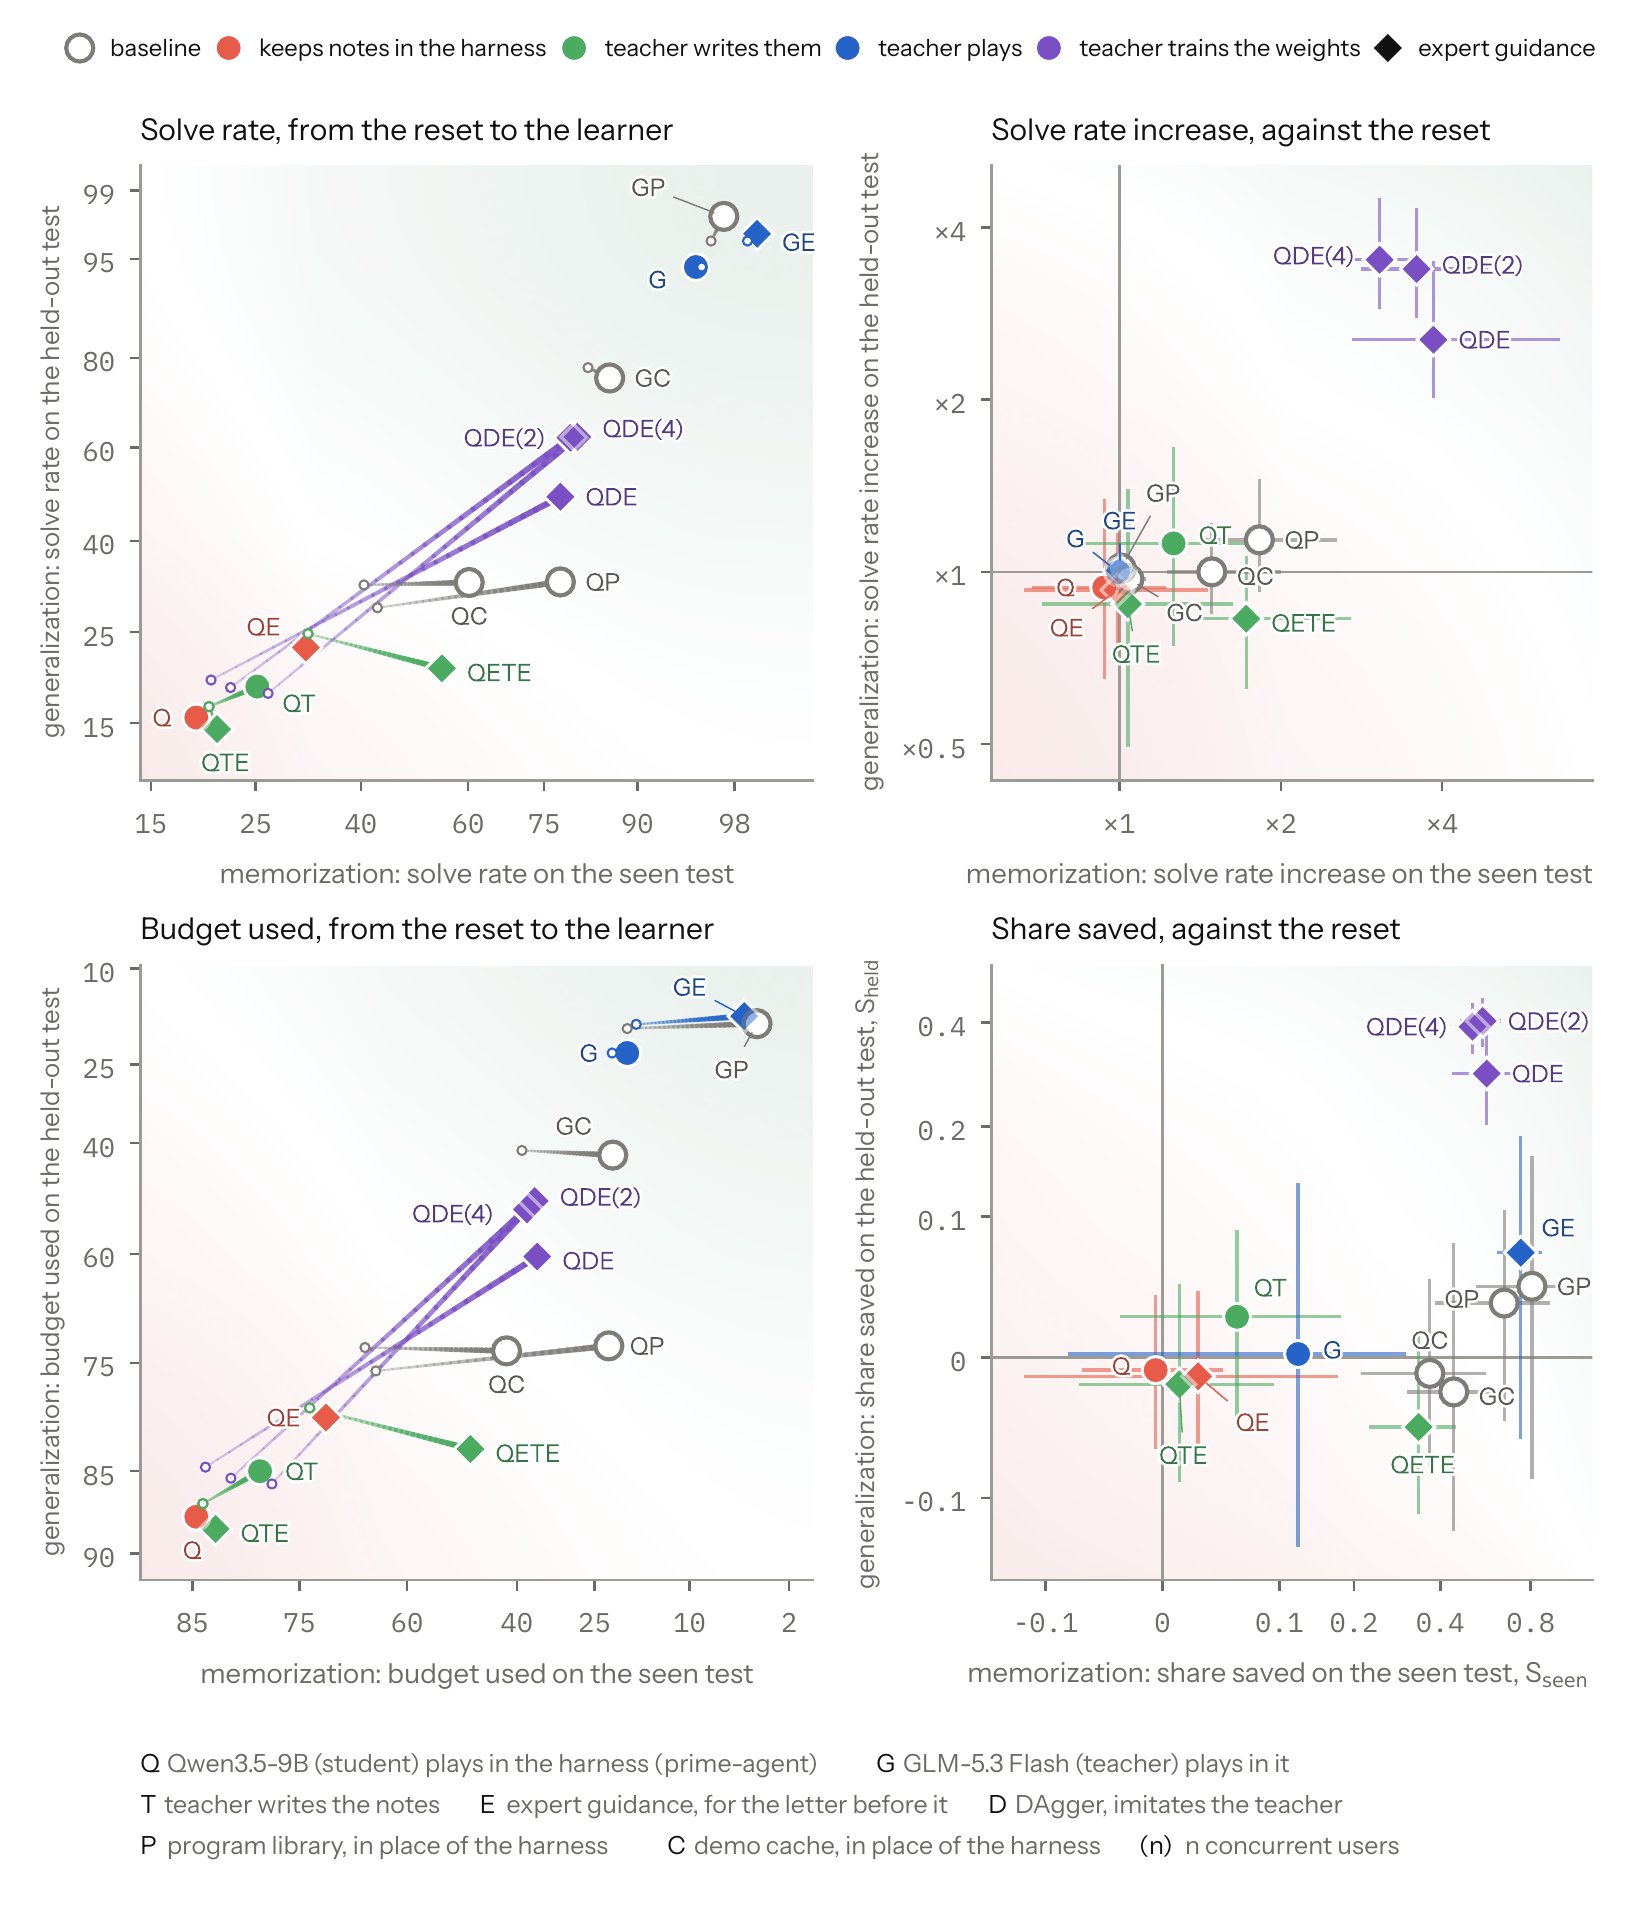
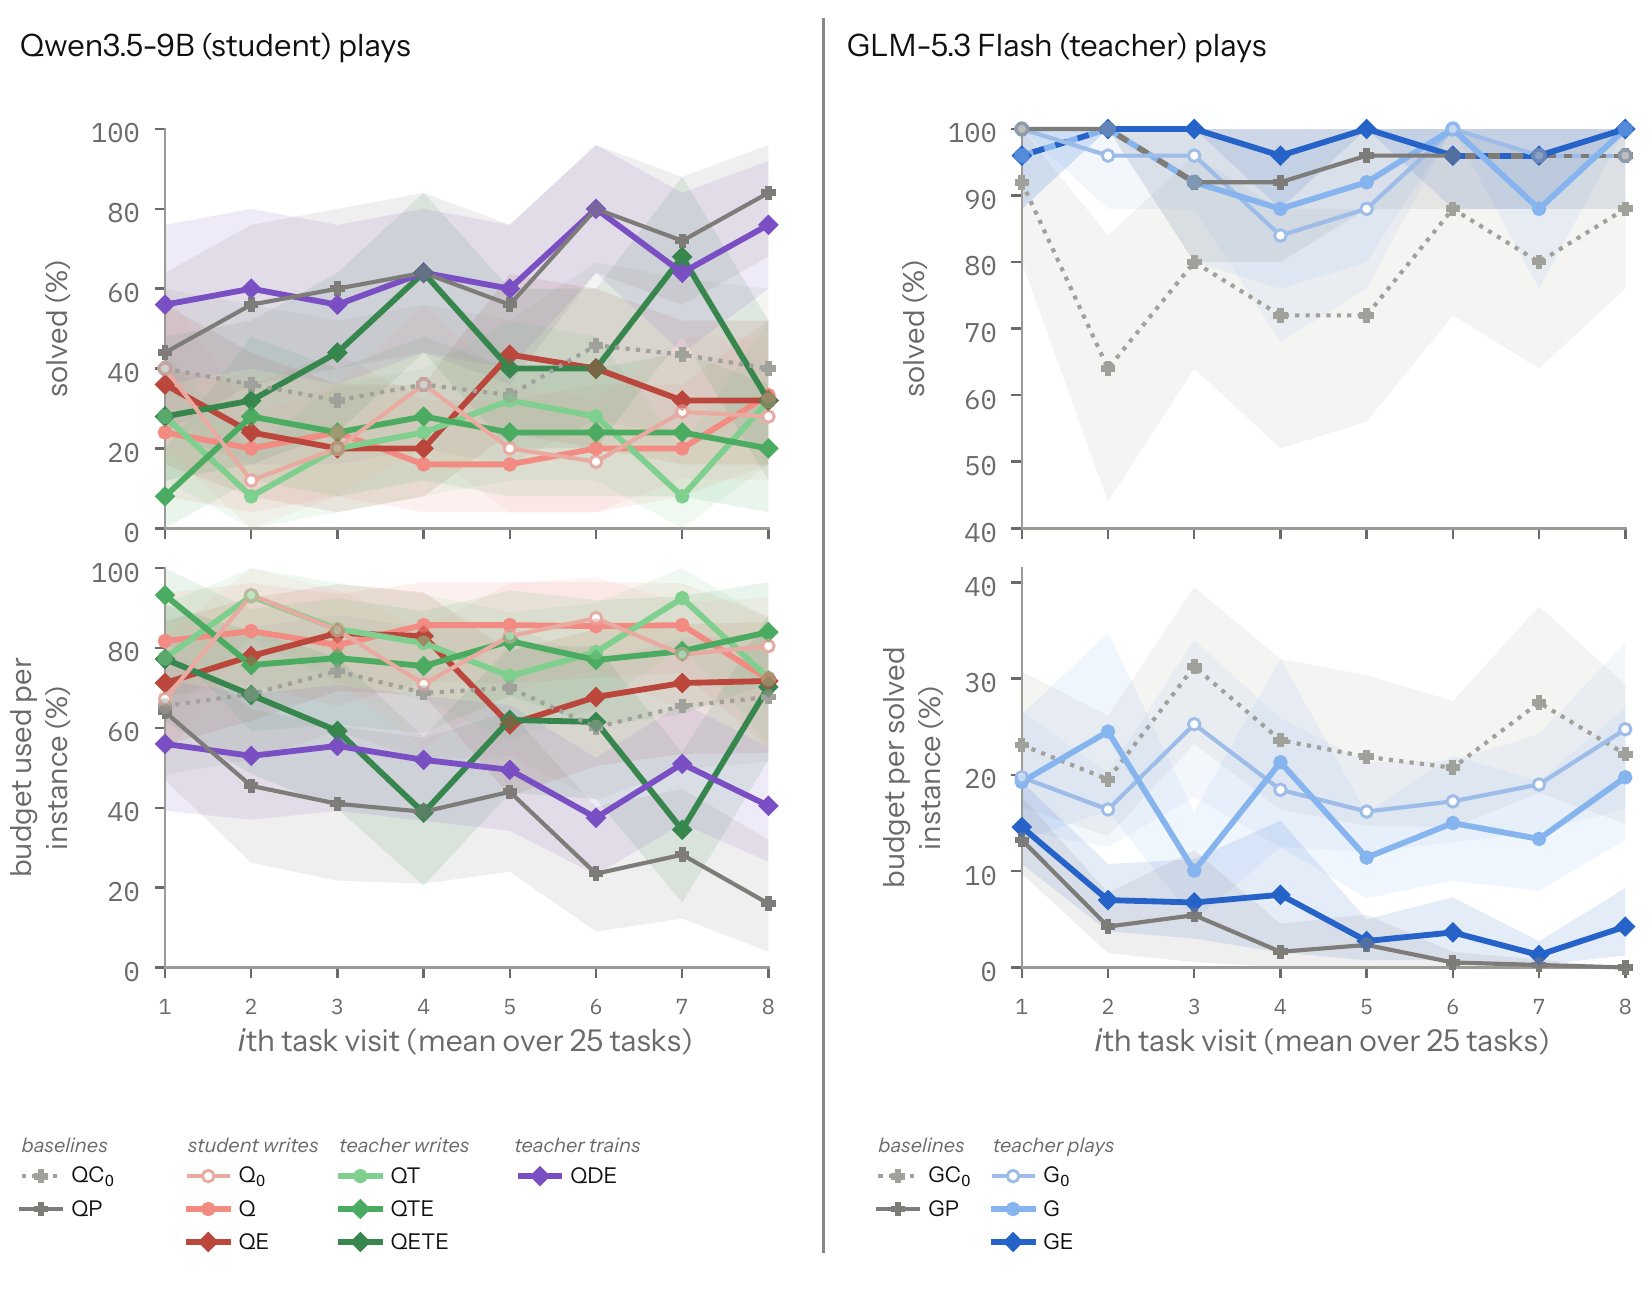
Notes against weights, on one open model: Qwen3.5-9B, taught by GLM-5.3 Flash.
Notes saved nothing measurable on new puzzles. Trained on GLM's moves (DAgger), Qwen spent 57% less than untrained on puzzles it had met, 29% less on 100 new ones.
Section 4 · continual-arc.unify.ai/experiments/qd
Notes saved nothing measurable on new puzzles. Trained on GLM's moves (DAgger), Qwen spent 57% less than untrained on puzzles it had met, 29% less on 100 new ones.
Section 4 · continual-arc.unify.ai/experiments/qd
3:12 PM UTC · Nov 11, 2026 · 5.1K Views
3615118
Daniel Lenton
@DanielLenton1
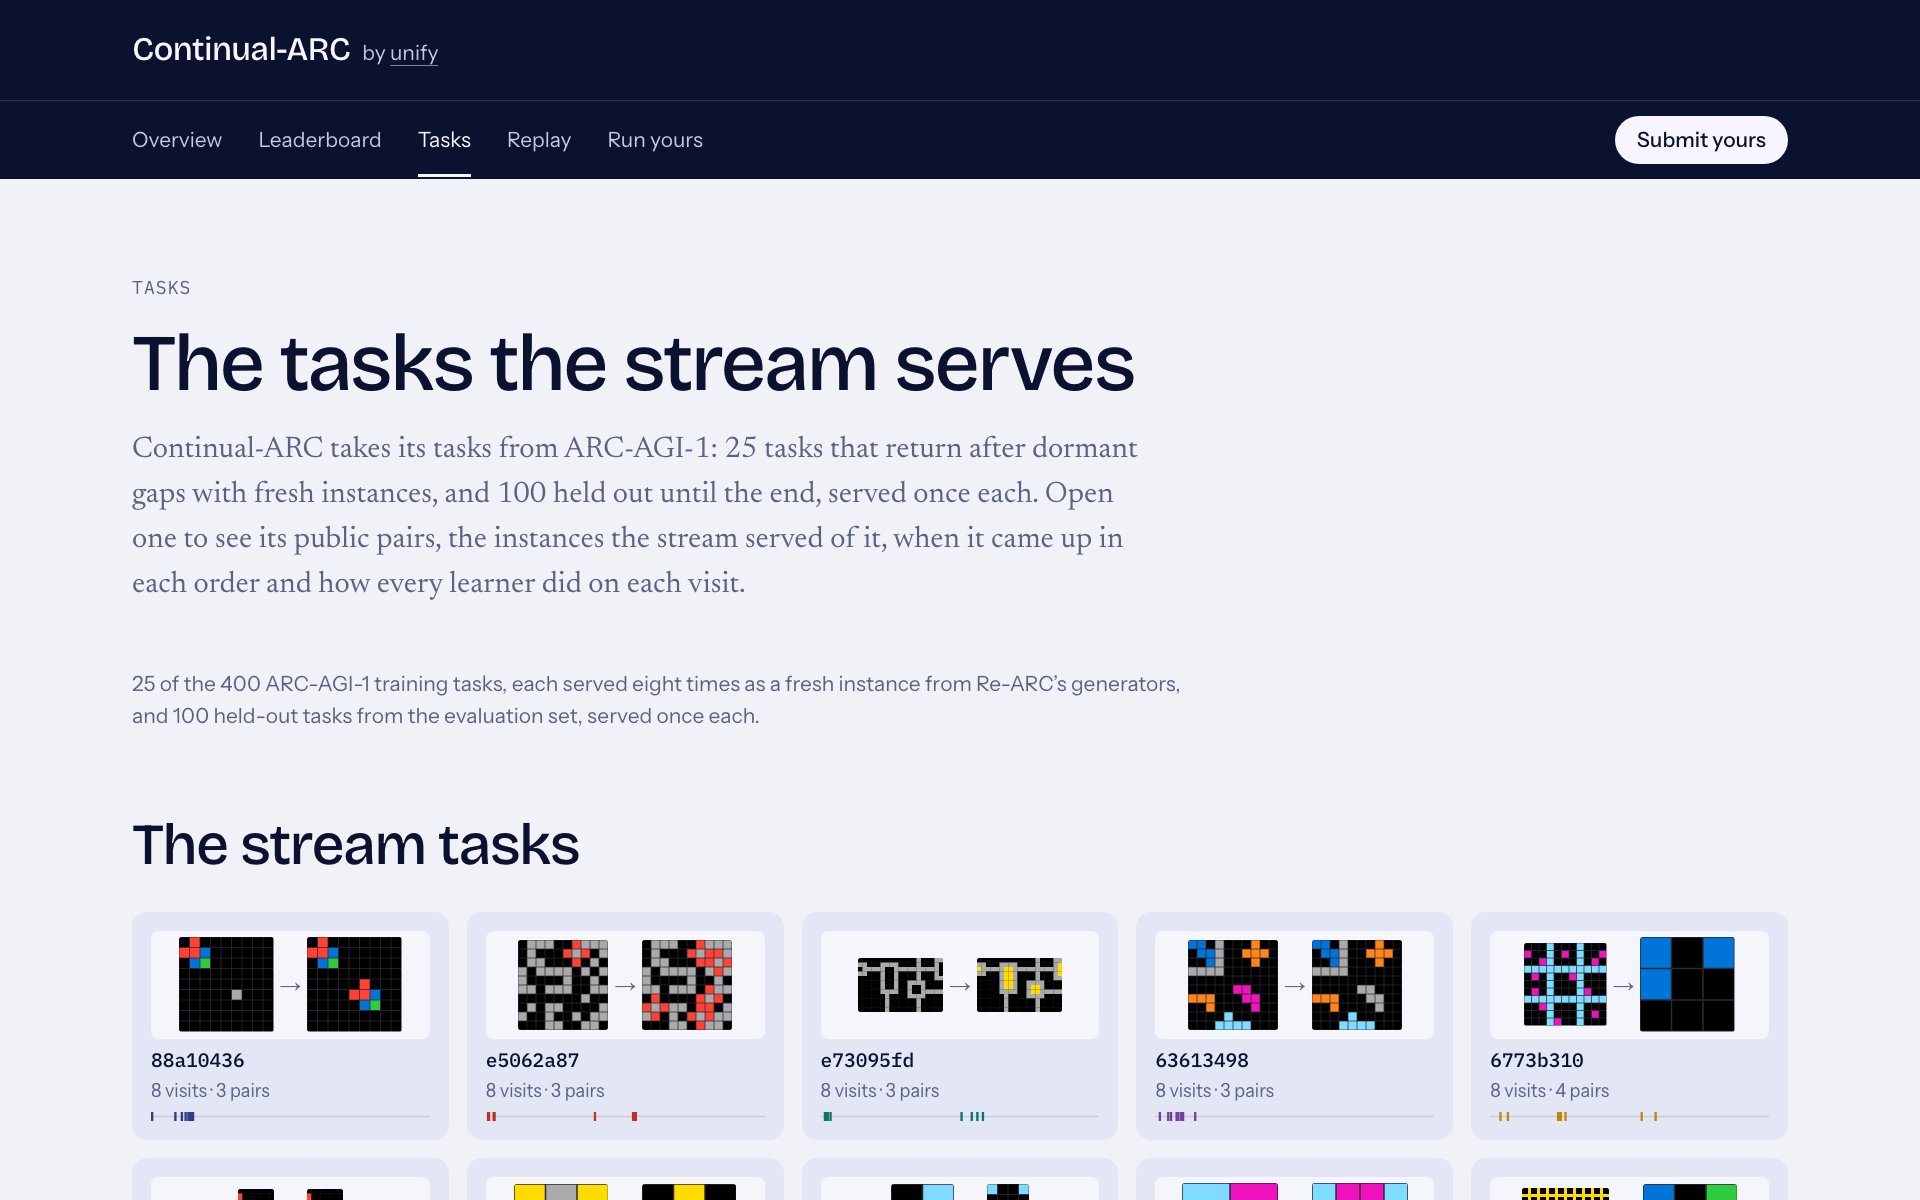
How it works: 25 ARC puzzles keep returning over a stream of 200 visits, each time with a new grid, so caching answers is useless.
After the stream, two tests: new grids of the puzzles it has seen, and 100 puzzles it has never seen.
Section 2 · continual-arc.unify.ai/tasks
After the stream, two tests: new grids of the puzzles it has seen, and 100 puzzles it has never seen.
Section 2 · continual-arc.unify.ai/tasks
3:12 PM UTC · Nov 11, 2026 · 3.3K Views
1514012
Daniel Lenton
@DanielLenton1
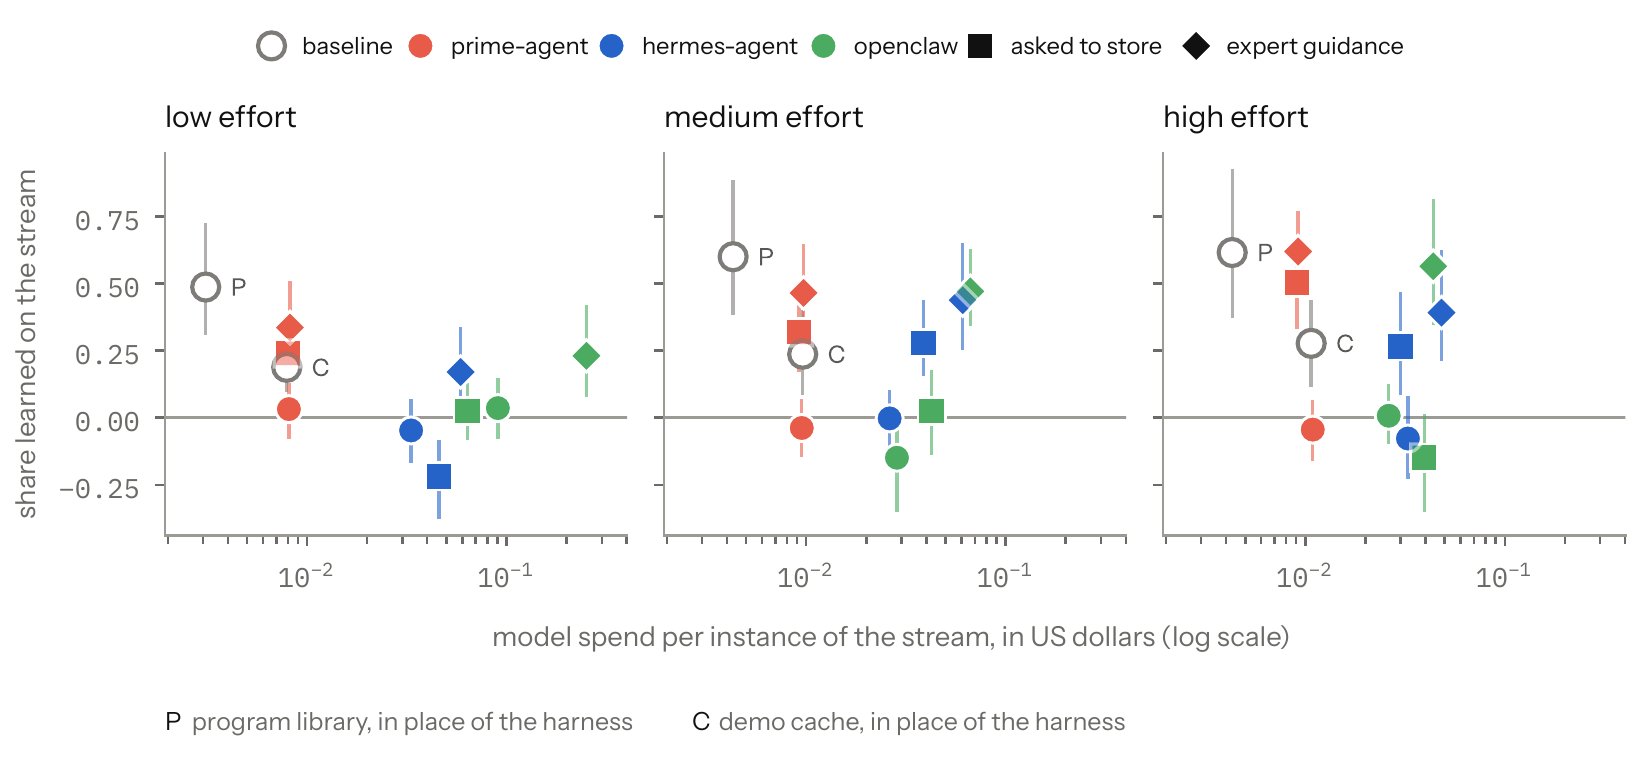
We ran all three on GPT-6 Luna. They solve 93 to 95% of puzzles at high effort, but never get cheaper as puzzles return. Remove their memory, and nothing changes.
A baseline that saves a program per puzzle drops straight away and stays down.
Appendix I · continual-arc.unify.ai/leaderboard
A baseline that saves a program per puzzle drops straight away and stays down.
Appendix I · continual-arc.unify.ai/leaderboard
3:12 PM UTC · Nov 11, 2026 · 2.9K Views
2514311
Daniel Lenton
@DanielLenton1
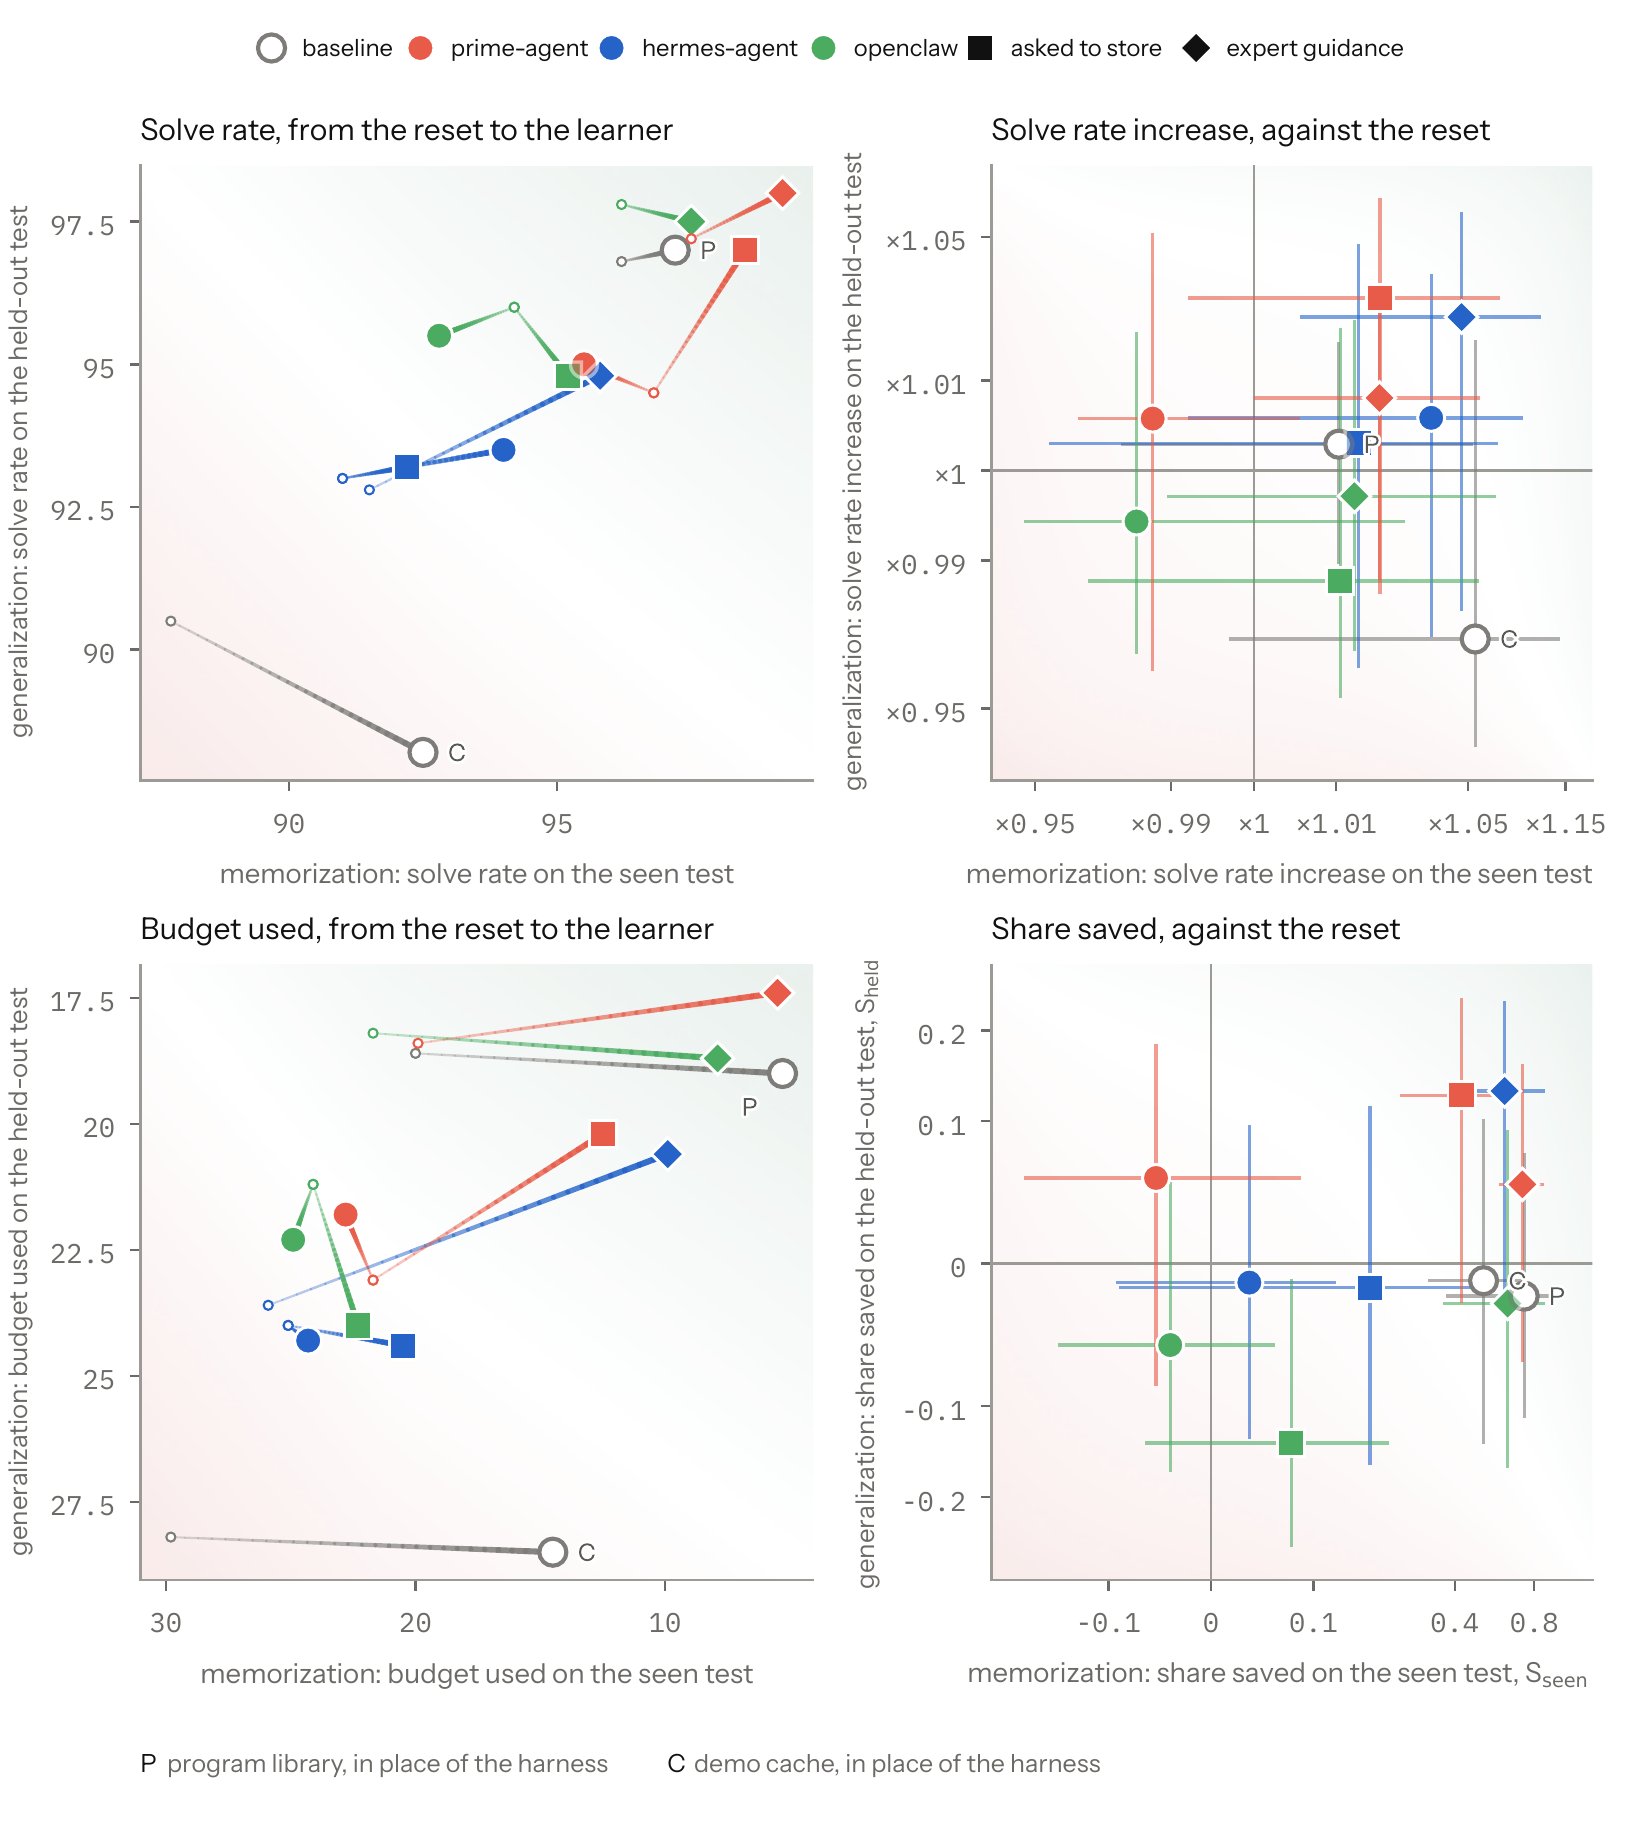
Told exactly what to keep, a checked program per puzzle, all three memorized, saving 17 to 62% of what perfect memory would.
But none got better at puzzles they'd never seen. The memory was there all along. The judgment wasn't.
Appendix F · continual-arc.unify.ai/leaderboard
But none got better at puzzles they'd never seen. The memory was there all along. The judgment wasn't.
Appendix F · continual-arc.unify.ai/leaderboard
3:12 PM UTC · Nov 11, 2026 · 2.7K Views
251389
Daniel Lenton
@DanielLenton1
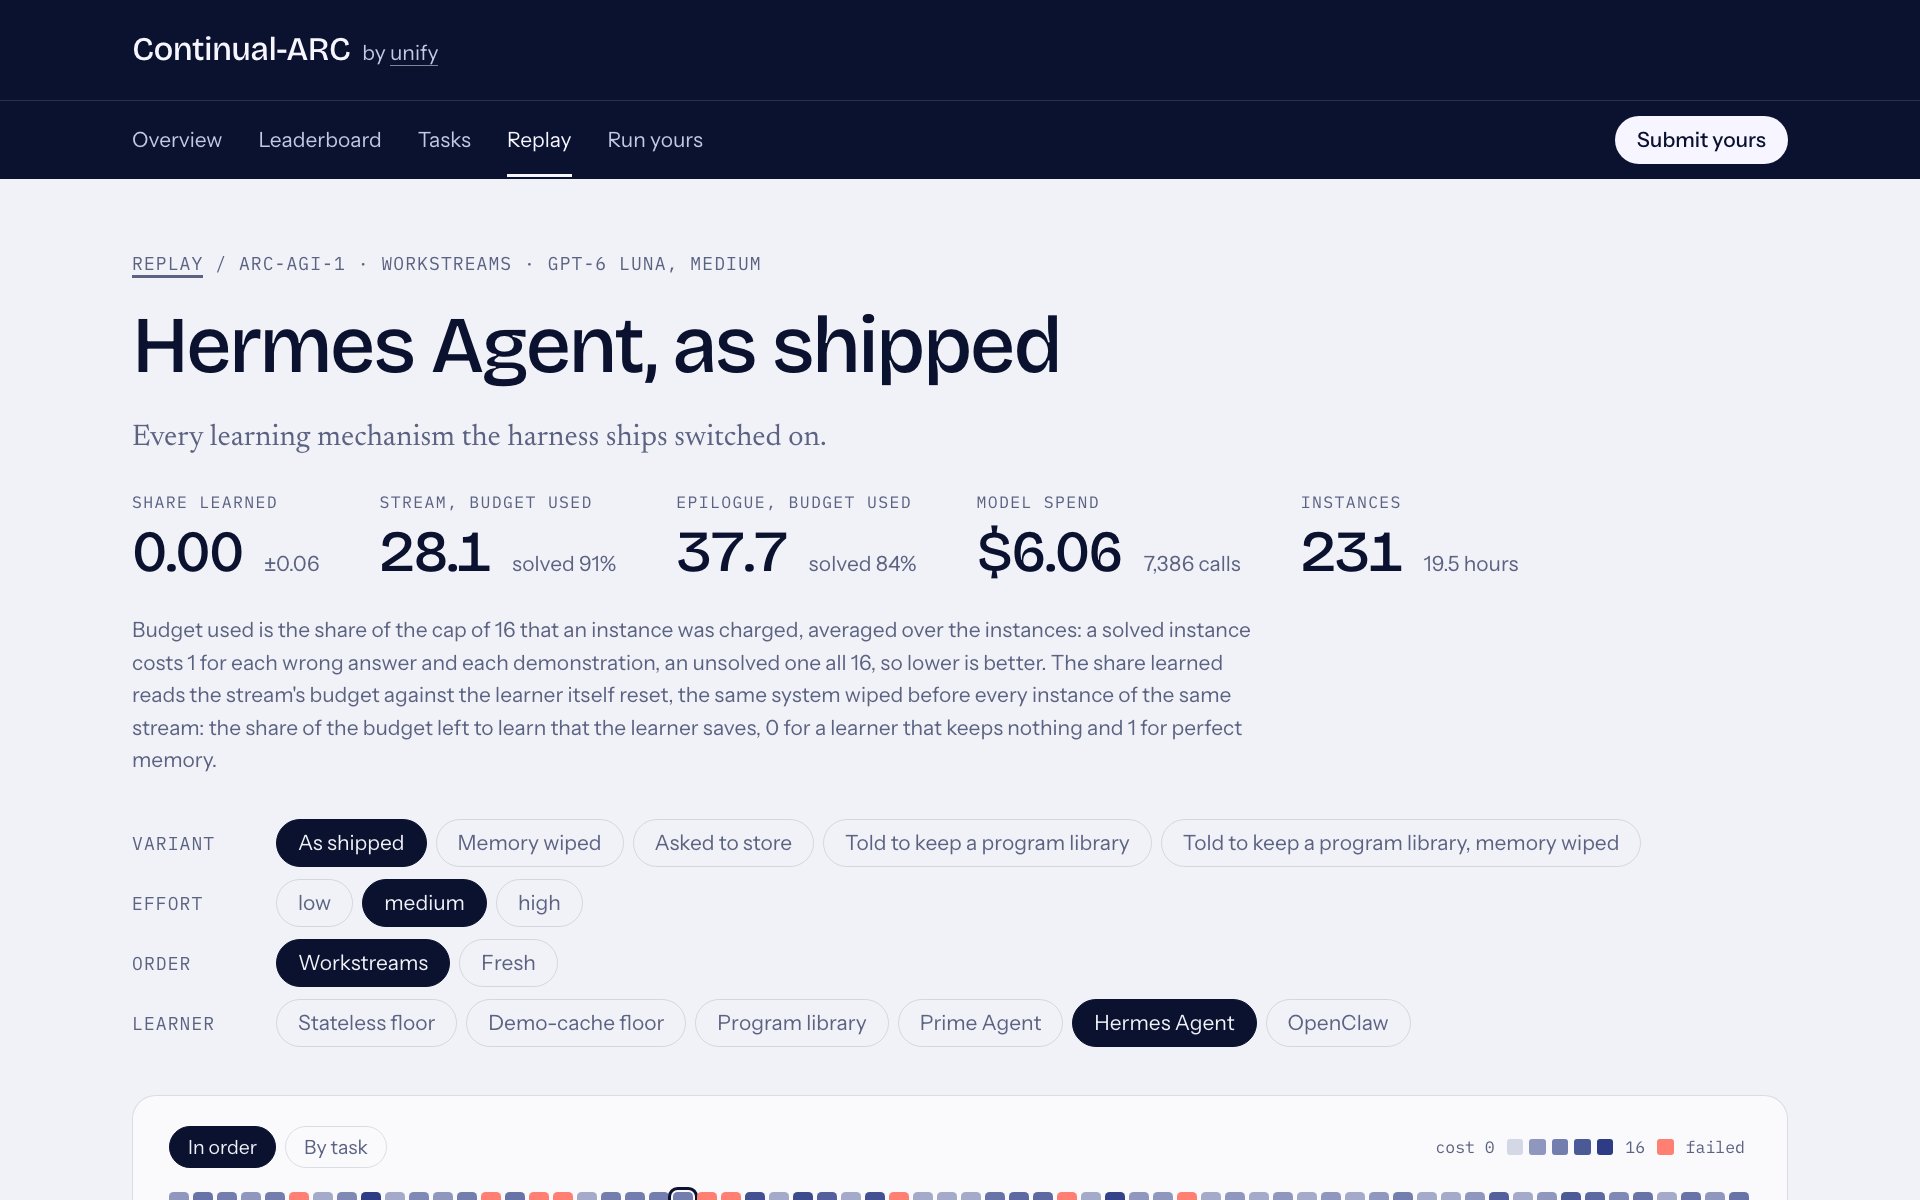
Why? Prime Agent never stored anything for later (its Python skills also failed to import for us). Hermes Agent opened a skill on 524 of 525 returns, but mostly general tips. OpenClaw kept every conversation, but rarely went back to look.
Appendix E · continual-arc.unify.ai/runs/arc1/H-he…
Appendix E · continual-arc.unify.ai/runs/arc1/H-he…
3:12 PM UTC · Nov 11, 2026 · 2.6K Views
2412912
Daniel Lenton
@DanielLenton1
Big caveat: one domain and a few models, none the strongest, and stronger ones may well keep more.
But I think real learning on the job will need the weights to change, with the harness becoming the thing that trains the model, not a growing pile of markdown files.
Section 6
But I think real learning on the job will need the weights to change, with the harness becoming the thing that trains the model, not a growing pile of markdown files.
Section 6
3:12 PM UTC · Nov 11, 2026 · 2.2K Views
141298
Daniel Lenton
@DanielLenton1
Think your harness or training method learns? Run it on the public stream, then get it verified: we rerun your code on 50 new puzzles nobody outside unify has seen.
Feedback of all kinds welcome, especially on where the benchmark falls short 🙏
continual-arc.unify.ai/submit
Feedback of all kinds welcome, especially on where the benchmark falls short 🙏
continual-arc.unify.ai/submit
continual-arc.unify.ai
Run yours · Continual-ARC
How to run Continual-ARC on your own learner or agent harness and have it verified: we rerun your code on a private set of new tasks for its track and present any verified submission of a genuine learning algorithm, novel or not.
3:12 PM UTC · Nov 11, 2026 · 2.1K Views
2512725