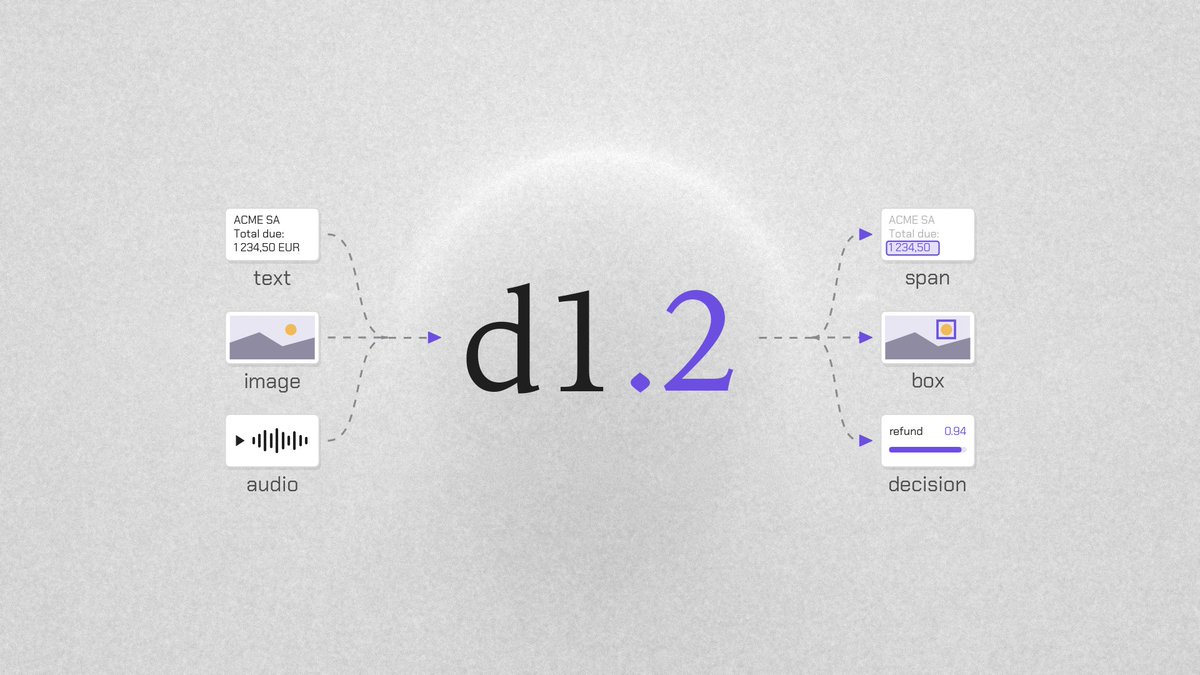
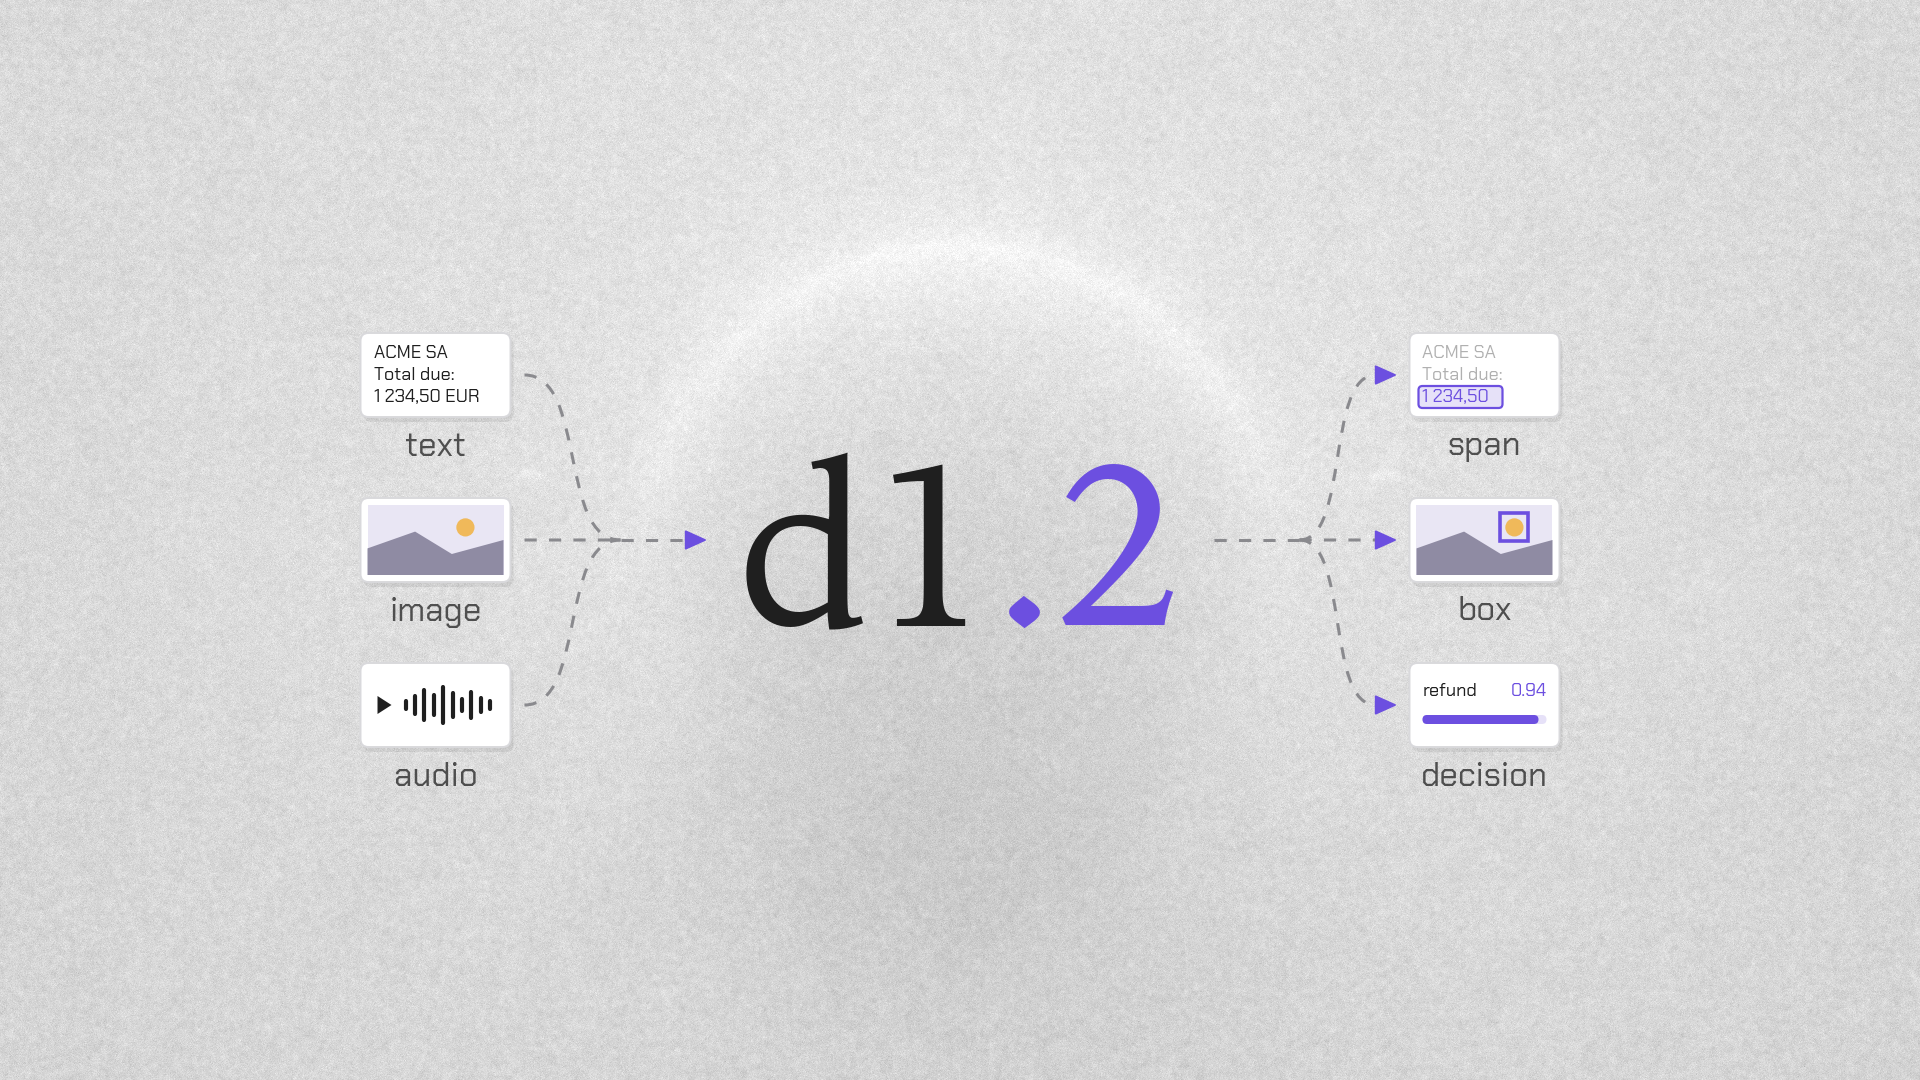
Today, we release d1.2 and d1.2-ultra, the state-of-the-art omnimodal decision models. d1.2 and d1.2-ultra both can process text, images, and audio with new output capabilities.
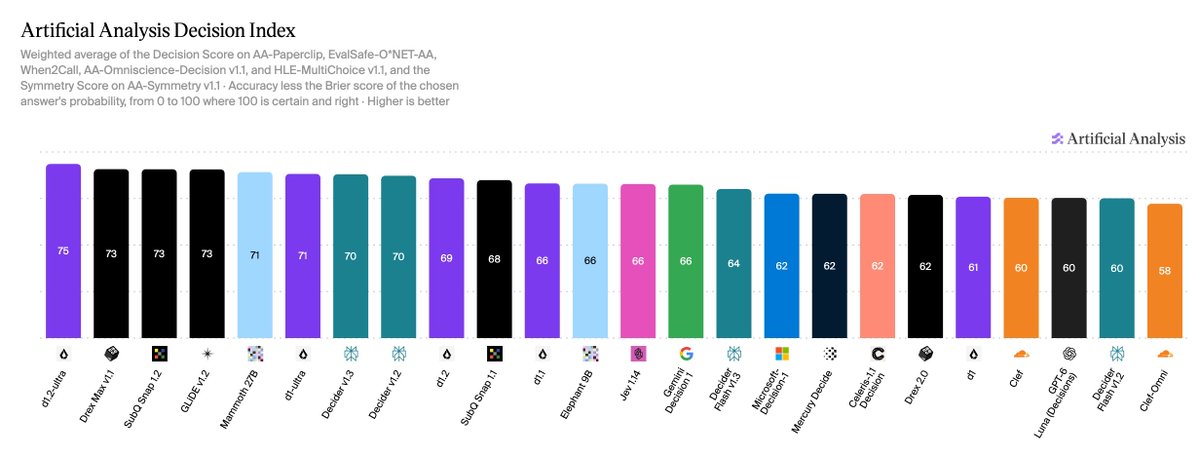
> #1 on the @ArtificialAnlys Decision Index (75)
> Read a value from the input (text, number or date)
> Find every passage of a kind in a text (spans)
> Locate things in a picture (box for one, boxes for every instance)
> Estimate a number (number with a range)
> Pick every option that applies (choice)
1/ 🧵
Liquid AI
@liquidai
d1.2-ultra ranks first among decision models on the @ArtificialAnalysis Decision Index v2.1, and for less than half its price, d1.2 offers the best trade-off between quality and cost. Both models are available today on the Liquid API, at $0.02 for d1.2 and $0.042 per million input tokens for d1.2-ultra.
/2
/2
3:08 PM UTC · Nov 16, 2026 · 19.4K Views
3614230
Liquid AI
@liquidai
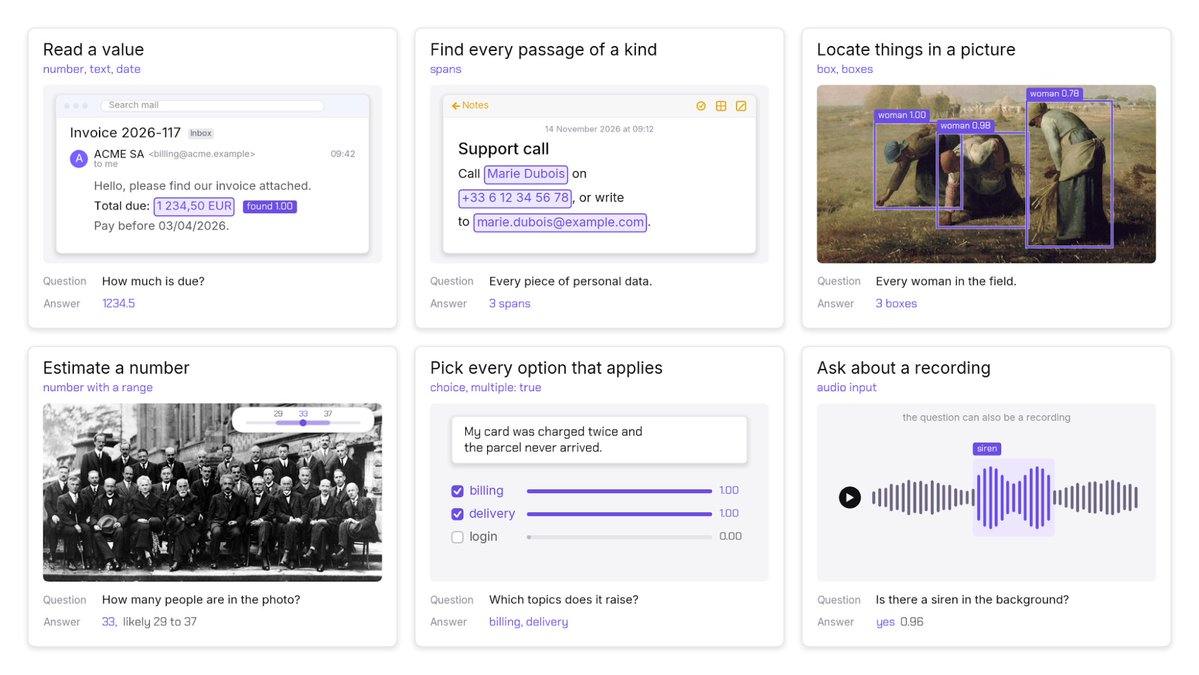
d1.2 and d1.2-ultra add five new tasks to the API:
> Read a value from the input (text, number or date). Ask "How much is due?" about an invoice, and the model returns the correct value with the characters it read it from. If the invoice doesn't show the value, it answers "not found" instead of guessing.
> Find every passage of a kind in a text (spans). For instance, ask for every piece of personal data in a note, and the model returns each passage, such as a name, a phone number, and an email address, with its position in the text.
> Locate things in a picture (box for one, boxes for every instance). For example, ask where the signature is on a scanned form, and the model returns a rectangle around it (or "not found"). Ask for every tree in a photo, and it returns a rectangle around each tree and the count.
> Estimate a number (number with a range). Ask how many people are in a photo, and the model returns its best guess (like 12, for example) and a range (like 10 to 14).
> Pick every option that applies (choice with multiple set to true). Ask which topics a support message raises, and the model returns each topic that applies, such as billing and delivery, each with its own probability.
d1.2 and d1.2-ultra also take audio as input. This audio input can be what you ask about; for example, which language someone speaks or whether there is a siren in the background. The question itself can also be a recording, spoken instead of typed.
/3
> Read a value from the input (text, number or date). Ask "How much is due?" about an invoice, and the model returns the correct value with the characters it read it from. If the invoice doesn't show the value, it answers "not found" instead of guessing.
> Find every passage of a kind in a text (spans). For instance, ask for every piece of personal data in a note, and the model returns each passage, such as a name, a phone number, and an email address, with its position in the text.
> Locate things in a picture (box for one, boxes for every instance). For example, ask where the signature is on a scanned form, and the model returns a rectangle around it (or "not found"). Ask for every tree in a photo, and it returns a rectangle around each tree and the count.
> Estimate a number (number with a range). Ask how many people are in a photo, and the model returns its best guess (like 12, for example) and a range (like 10 to 14).
> Pick every option that applies (choice with multiple set to true). Ask which topics a support message raises, and the model returns each topic that applies, such as billing and delivery, each with its own probability.
d1.2 and d1.2-ultra also take audio as input. This audio input can be what you ask about; for example, which language someone speaks or whether there is a siren in the background. The question itself can also be a recording, spoken instead of typed.
/3
3:08 PM UTC · Nov 16, 2026 · 9.3K Views
4110423
Liquid AI
@liquidai
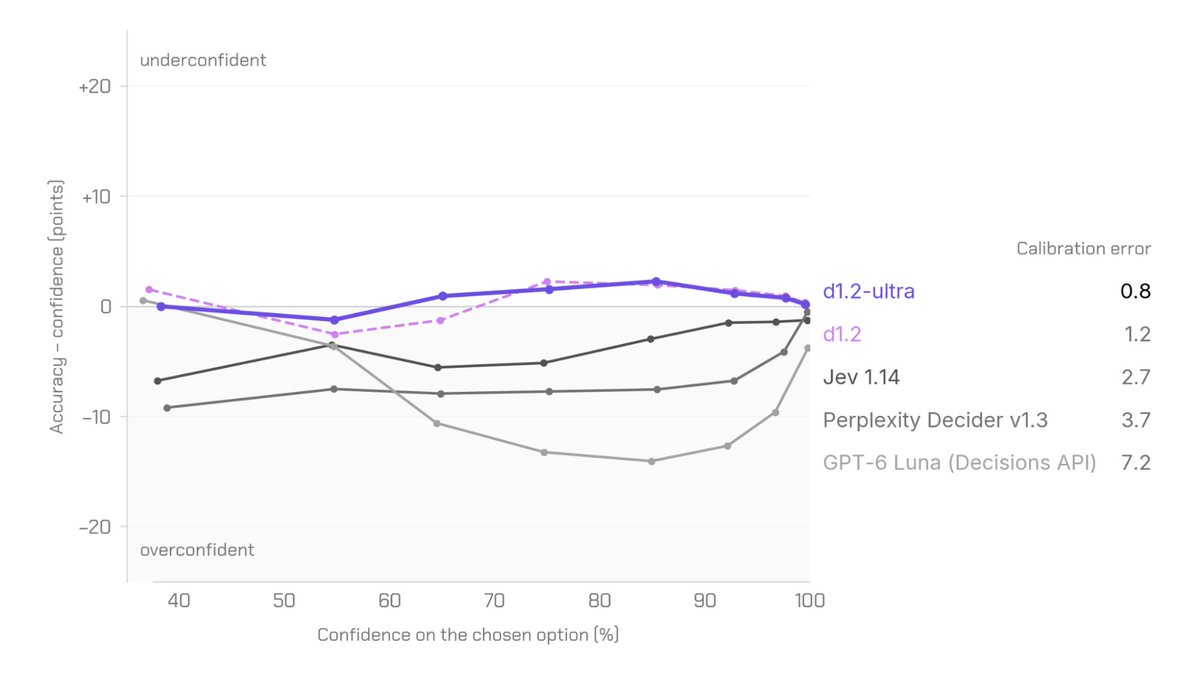
Calibration - the probabilities provided by a decision model are only useful if they're correct. When it says 80%, it should be right about 80% of the time, which lets you set a threshold. For example, you can automatically send tasks where the model has low confidence to human review.
Calibration error measures the gap between a model's predicted probability and how often it is right. Across 13 benchmarks and 22,505 questions answered by all five models, d1.2-ultra's calibration error is 0.8 points, compared with 1.2 for d1.2, 2.7 for Jev 1.14, 3.7 for Perplexity's Decider v1.3, and 7.2 for GPT-6 Luna on its Decisions API.
4/
Calibration error measures the gap between a model's predicted probability and how often it is right. Across 13 benchmarks and 22,505 questions answered by all five models, d1.2-ultra's calibration error is 0.8 points, compared with 1.2 for d1.2, 2.7 for Jev 1.14, 3.7 for Perplexity's Decider v1.3, and 7.2 for GPT-6 Luna on its Decisions API.
4/
3:08 PM UTC · Nov 16, 2026 · 7.5K Views
31615
Liquid AI
@liquidai
d1.2 and d1.2-ultra are available at the same price of d1.1 and d1-ultra. You only pay for inputs, there are no output tokens.
> Read the blog: liquid.ai/blog/d1-2
> AA Decision Index: artificialanalysis.ai/evaluations/artif…
> Start building: console.liquid.ai/
> @openrouter (coming soon)
> @vercel (coming soon)
> we will open the weights at some point.
> Read the blog: liquid.ai/blog/d1-2
> AA Decision Index: artificialanalysis.ai/evaluations/artif…
> Start building: console.liquid.ai/
> @openrouter (coming soon)
> @vercel (coming soon)
> we will open the weights at some point.
liquid.ai
d1.2: State-of-the-Art Omnimodal Decision Models | Blog
Introducing Liquid AI’s d1.2 and d1.2-ultra, state-of-the-art omnimodal decision models with audio support, five new tasks, and industry-leading accuracy.
3:08 PM UTC · Nov 16, 2026 · 6.6K Views
5410730