Introducing Model Factory.
Train, deploy, and continuously improve your own models on one stack.
Run on-demand, on dedicated clusters, or bring your own.
Own your intelligence. Own your model factory.
Prime Intellect
@PrimeIntellect
Frontier labs own the full loop, training and deploying intelligence, and capturing the data required to train the next model.
We believe every company should have that same ability.
Model Factory brings that loop into one open, customizable stack. Here's how it works:
We believe every company should have that same ability.
Model Factory brings that loop into one open, customizable stack. Here's how it works:
12:12 AM UTC · Nov 19, 2026 · 15.1K Views
1712638
Prime Intellect
@PrimeIntellect
Train agents with reinforcement learning.
+ Large-scale async RL with managed prime-rl
+ Your tasks, environments, and rewards
+ verifiers, Environments Hub, and Harbor support
+ Thousands of concurrent sandboxes for agents that write code and use tools
+ Large-scale async RL with managed prime-rl
+ Your tasks, environments, and rewards
+ verifiers, Environments Hub, and Harbor support
+ Thousands of concurrent sandboxes for agents that write code and use tools
12:12 AM UTC · Nov 19, 2026 · 2.8K Views
11546
Prime Intellect
@PrimeIntellect
Pre-train. Mid-train. Run your own research.
+ Scale to thousands of GPUs with automatic recovery from node failures
+ Train efficiently with Prime Mega MoE: 48% MFU on H200s with Qwen’s 235B MoE
+ Explore new architectures and objectives, run ablations and launch autonomous training experiments
+ Scale to thousands of GPUs with automatic recovery from node failures
+ Train efficiently with Prime Mega MoE: 48% MFU on H200s with Qwen’s 235B MoE
+ Explore new architectures and objectives, run ablations and launch autonomous training experiments
12:12 AM UTC · Nov 19, 2026 · 2.2K Views
11544
Prime Intellect
@PrimeIntellect
Fine-tune on your own data.
+ Run supervised fine-tuning with hosted SFT
+ Evaluate checkpoints throughout training to see whether your model is getting better at your tasks
Build the starting point for your next RL run.
+ Run supervised fine-tuning with hosted SFT
+ Evaluate checkpoints throughout training to see whether your model is getting better at your tasks
Build the starting point for your next RL run.
12:12 AM UTC · Nov 19, 2026 · 1.9K Views
11464
Prime Intellect
@PrimeIntellect
Agents and RL need somewhere safe to run.
+ Model Factory integrates Prime Sandboxes: hardware-isolated microVMs you can spin up, checkpoint, fork, and lock down
+ Built for RL, they easily scale into the tens of thousands
+ Model Factory integrates Prime Sandboxes: hardware-isolated microVMs you can spin up, checkpoint, fork, and lock down
+ Built for RL, they easily scale into the tens of thousands
12:12 AM UTC · Nov 19, 2026 · 1.7K Views
11412
Prime Intellect
@PrimeIntellect
Deploy the model you trained.
+ One click from checkpoint to inference endpoint
+ Run evaluations and synthetic data generation at scale
+ Training and inference on the same infrastructure
+ One click from checkpoint to inference endpoint
+ Run evaluations and synthetic data generation at scale
+ Training and inference on the same infrastructure
12:12 AM UTC · Nov 19, 2026 · 1.6K Views
11403
Prime Intellect
@PrimeIntellect
Turn production experience into your next training run.
Enable trace collection with Prime Traces. Inspect what your agents actually do, find where they fail, and turn those failures into environments.
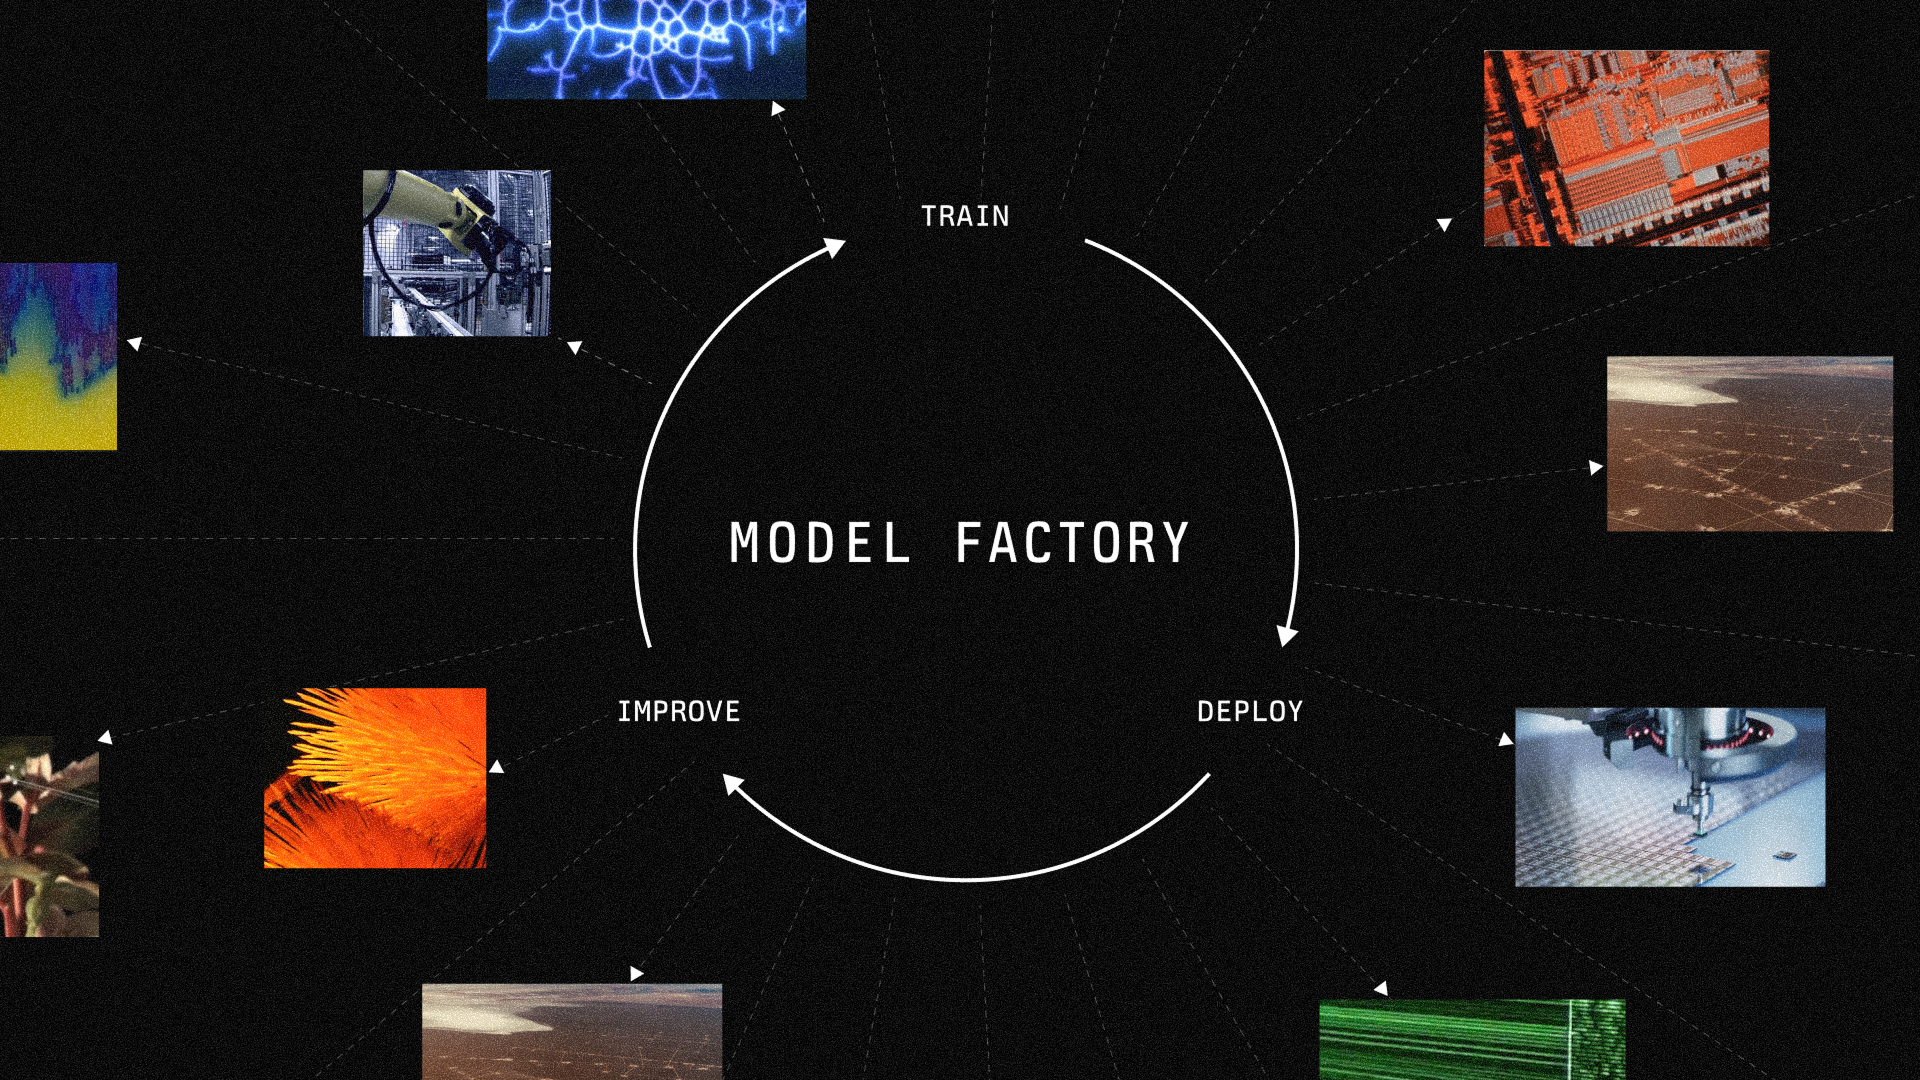
Deploy → collect traces → evaluate → train → repeat.
Enable trace collection with Prime Traces. Inspect what your agents actually do, find where they fail, and turn those failures into environments.
Deploy → collect traces → evaluate → train → repeat.
12:12 AM UTC · Nov 19, 2026 · 1.5K Views
11422
Prime Intellect
@PrimeIntellect
The foundation: self-healing compute.
+ Health checks and automatic node replacement
+ Automatic recovery from the latest checkpoint
+ Move GPUs between workloads through the prime factory CLI
Dedicated Model Factory deployments bring training, inference, Slurm and Kubernetes access onto the same fabric, across all your compute.
+ Health checks and automatic node replacement
+ Automatic recovery from the latest checkpoint
+ Move GPUs between workloads through the prime factory CLI
Dedicated Model Factory deployments bring training, inference, Slurm and Kubernetes access onto the same fabric, across all your compute.
12:13 AM UTC · Nov 19, 2026 · 1.4K Views
11443
Prime Intellect
@PrimeIntellect
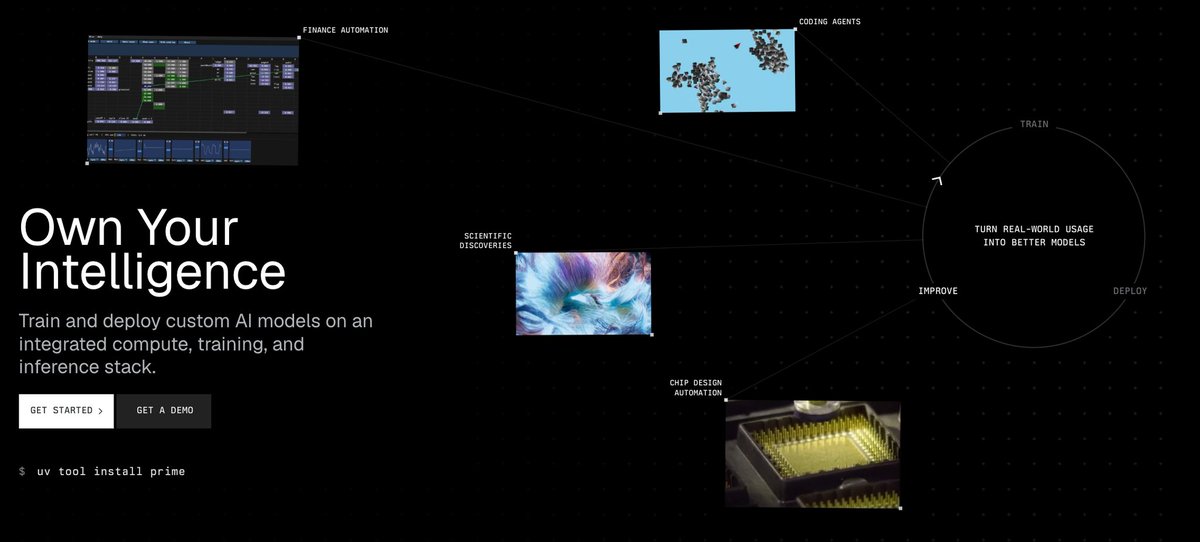
We’re already deploying Model Factory for teams working on finance automation, computer use, scientific discovery, chip design and more.
Their data. Their environments. Their models. A factory built around what they need.
Starting today, we’re putting those same capabilities in your hands.
Their data. Their environments. Their models. A factory built around what they need.
Starting today, we’re putting those same capabilities in your hands.
12:13 AM UTC · Nov 19, 2026 · 1.4K Views
11402
Prime Intellect
@PrimeIntellect
Get started docs.primeintellect.ai/hosted-trainin…
docs.primeintellect.ai
Getting Started - Prime Intellect Docs
Launch your first on-demand Hosted Training run
12:13 AM UTC · Nov 19, 2026 · 1.3K Views
11406
Prime Intellect
@PrimeIntellect
Book a call to get a demo, and explore dedicated Model Factory capacity primeintellect.ai/contact
primeintellect.ai
Contact | Prime Intellect
Train, deploy, and continuously improve your own models on an integrated compute, training, inference, and sandbox stack.
12:13 AM UTC · Nov 19, 2026 · 1.8K Views
11292
Prime Intellect
@PrimeIntellect
Read our blog post here primeintellect.ai/blog/introduci…
Own your model factory. Own the means of production.
Own your model factory. Own the means of production.
primeintellect.ai
Introducing Model Factory
Today we introduce Model Factory: the loop that frontier labs run on. Now, any company can train, deploy, and continuously improve models in production.
12:13 AM UTC · Nov 19, 2026 · 2.5K Views
275712